
Where This Concept Fits
Concepts Covered — Attention Learning Tree
What Theory Should You Learn?
Attention in Four Levels
Why Was Attention Needed?
Complete Internal Working Flow
Important Components / Subconcepts
One Agentic AI Example
Compare with Closely Related Concepts
Relationship with Previous and Next Concepts
What Should I NOT Learn Now?
Practical Experiments
Code Only When It Helps Learning
Architecture Diagrams
Mental Model
Important Terminology
Contrast Pairs
Terms You Must Be Able to Use
Subjective / Explain-It Questions
Objective / MCQs
Where This Concept Fits
Transformer
    ↓
Attention          ← YOU ARE HERE
    ↓
Tokens / Tokenization
    ↓
Embeddings
    ↓
LLM Fundamentals
    ↓
Prompt Engineering
    ↓
RAG
    ↓
Tools / Function Calling
    ↓
AI Agent
    ↓
State + Memory + Workflow
    ↓
Production Agentic AI
Why learn Attention now?
You already learned:

Text
 ↓
Tokens
 ↓
Transformer
 ↓
Contextual representation
 ↓
Next-token prediction
But one major question is still unanswer
How does the Transformer know which other tokens matter to the current token?
answer is Attention
If you skip Attention, what breaks later?
You may still be able to call an LLM API, but several things will remain mysterious:
Why changing a few prompt words can change the answer.
Why instructions far apart can still influence generation.
Why ambiguous context causes incorrect interpretation.
Why long context increases computation.
Why context ordering matters.
Why an LLM can connect "it" with an earlier noun.
Why irrelevant retrieved RAG chunks can hurt answers.
Why an agent can misinterpret tool descriptions.
Why Transformer and Attention are not the same thing.
Concepts Covered — Attention Learning Tree
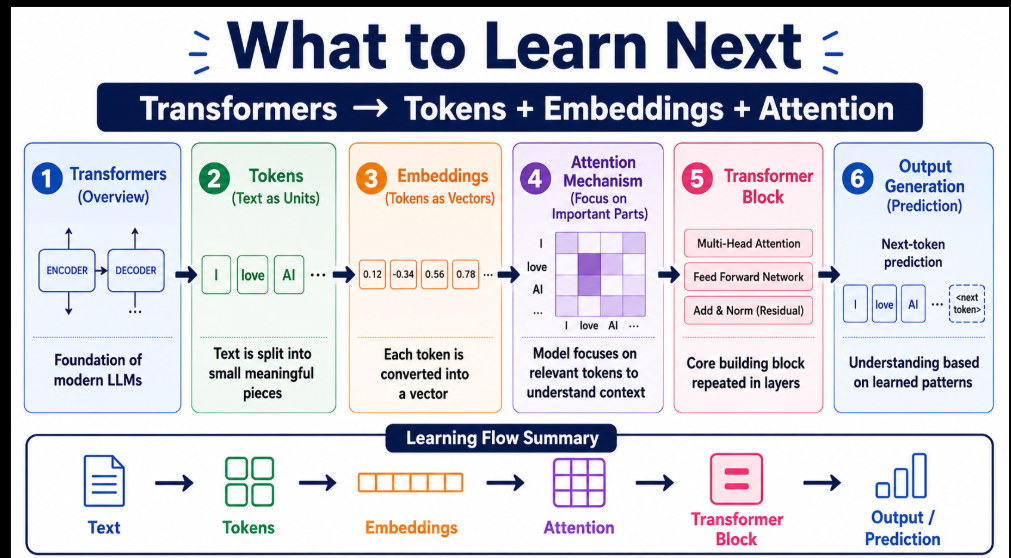
Transformer foundation
        ↓
What is Attention?
        ↓
Why Attention?
        ↓
Self-Attention
        ↓
Token-to-token relationships
        ↓
Query / Key / Value
        ↓
Relevance scores
        ↓
Attention weights
        ↓
Weighted information combination
        ↓
Contextual representation
        ↓
LLM understanding/generation
        ↓
Future: prompts / RAG / tools / agents
The roadmap explicitly requires what Attention means, why it is needed, self-attention, token dependence, high-level Q/K/V, attention weights, and context dependence.
Must Learn Now
What Attention means.
Why Attention exists.
Self-attention.
Token-to-token relationships.
Query at a conceptual level.
Key at a conceptual level.
Value at a conceptual level.
Relevance/attention score.
Attention weights.
Weighted combination of information.
Contextual representation.
Context dependence.
Learn at High Level
Causal/masked self-attention.
Multi-head attention.
Softmax.
Why multiple Transformer layers repeat contextual processing.
Why long sequences make attention more expensive.
The original Transformer uses scaled dot-product attention and multiple parallel attention heads; however, for your roadmap, understanding their purpose is enough rather than reproducing the equations.
Learn Later
Cross-attention in depth.
KV cache.
FlashAttention.
Grouped-query attention.
Multi-query attention.
Sparse attention.
Sliding-window attention.
Attention optimization for extremely long contexts.
Attention-head analysis.
Multimodal attention architectures.
Do Not Learn Yet
Deriving Q×Kᵀ mathematically.
Matrix calculus.
Attention backpropagation.
Gradient derivations.
Building an attention layer from scratch in PyTorch.
GPU kernels.
CUDA attention implementation.
Training Transformers from scratch.
Your roadmap specifically says Q/K/V calculations, Transformer mathematics, backpropagation, model training, GPU architecture, PyTorch, and TensorFlow are unnecessary at this stag
What Theory Should You Learn?
Keep the learning balance:
Theory                    ≈ 30%
Practical experiments     ≈ 50%
Debug / Compare / Explain ≈ 20%
That is the Project 0 balance defined by your roadmap.
3.1 Definition
Simple definition:
Attention is the mechanism that lets a token determine which other relevant tokens it should use when building its contextual representation.
Technical version:
Attention computes relevance between representations and uses those relevance weights to combine information from value representations.
The original Transformer made attention central to its architecture rather than relying on recurrent processing.
3.2 Why does it exist?
Consider:
The animal didn't cross the street because it was tired.
To interpret:
"it"
the model needs information associated with:
"animal"
The roadmap uses exactly this kind of dependency to explain why Attention matters.
Without contextual relationships:
"it"
 ↓
???
With Attention:
"it"
 ↓
check relevant tokens
 ↓
animal ← strong relationship
street ← weaker relationship
tired  ← useful context
 ↓
contextual meaning
3.3 Before Attention-centric Transformers
Earlier sequence architectures commonly processed sequences recurrently:
Token 1
  ↓
Token 2
  ↓
Token 3
  ↓
Token 4
Transformers instead use attention as their central sequence-interaction mechanism and remove recurrence, enabling much more parallel sequence processing during training.
3.4 How Attention works
At your required depth:
Current token
      ↓
asks: "What information do I need?"
      ↓
Query
      ↓
compared against Keys of available tokens
      ↓
Relevance scores
      ↓
Attention weights
      ↓
use weights to combine Values
      ↓
Context-aware representation
3.5 Why this matters to an Agentic AI Engineer
Later:
User:
"Find cardiologists in Delhi available tomorrow."
The LLM must correctly relate:
cardiologists ← find
Delhi         ← location
tomorrow      ← availability date
Attention contributes to those internal context-sensitive representations.
But Attention does not itself call the hospital API.
That distinction becomes extremely important later.
Attention in Four Levels
Level 1 — One-Line Explanation
Attention lets each token decide which other tokens are relevant to its current meaning.
Level 2 — Beginner Explanation
Imagine reading:
The doctor told Ravi that his appointment was cancelled.
When you read:
his appointment
you naturally connect "his" with "Ravi".
An AI model needs a mechanism to build useful connections among tokens too.
Attention is one of those mechanisms.
his
 ↓
look at relevant earlier information
 ↓
Ravi receives high relevance
 ↓
better contextual representation
Level 3 — Developer Explanation
Think about Attention like dynamic dependency resolution.
Traditional code might contain explicit relations:
appointment.user_id = ravi.id
Language doesn't provide explicit foreign keys.
Instead:
Tokens
   ↓
generate Q/K/V representations
   ↓
calculate relevance
   ↓
assign weights
   ↓
combine useful information
   ↓
contextual token representations
The model learns these transformations during training; your application doesn't manually define them.
Why Was Attention Needed?
Older mental model
RNN-style sequence processing
Token 1
  ↓ state
Token 2
  ↓ state
Token 3
  ↓ state
Token 4
Information moves through a recurrent sequence.
Limitation
Suppose:
The customer who booked the red SUV after speaking
with our Delhi support team cancelled it.
To interpret:
it
information associated with "SUV" may need to influence a later position.
Attention creates more direct token-to-token information paths instead of requiring all useful information to be carried only through recurrent state. The Transformer paper removed recurrence entirely and based the architecture around attention.
New approach
customer ──────────────┐
red      ─────→ SUV    │
Delhi    ─→ support    │
SUV      ───────────→ it
                       │
cancelled ←────────────┘
What improved?
Not simply:
"Attention is better."
More precisely:
Old recurrent approach
       ↓
sequence processed through recurrent state
       ↓
long dependency path + sequential computation

Attention-based approach
       ↓
positions can directly exchange relevant information
       ↓
easier modelling of relationships
+
far more parallel computation during training
That parallelizability was a major motivation and result of the original Transformer architectur
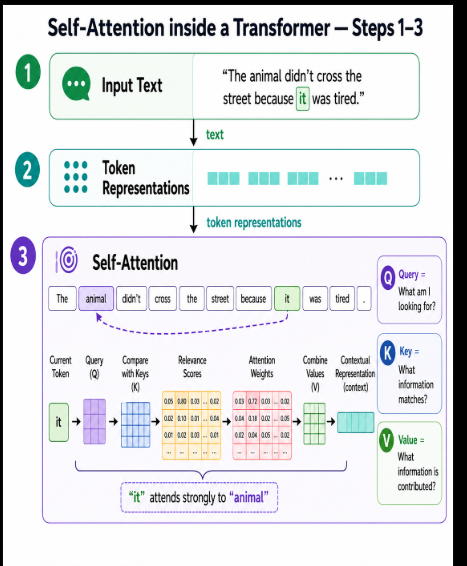
Complete Internal Working Flow
Suppose input contains:
"The animal didn't cross the street because it was tired."
Focus on the token representing "it".
Input token representations
          ↓
Create Q, K, V representations
          ↓
Query from "it"
          ↓
Compare Query against Keys
          ↓
animal → strong relevance
street → weaker relevance
tired  → useful relation

          ↓
Create relevance scores
          ↓
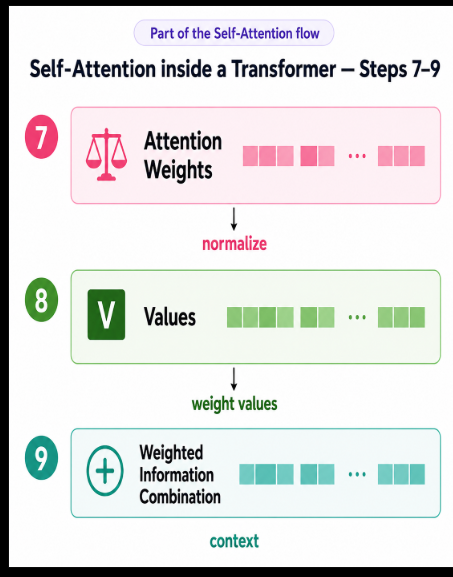
Normalize into attention weights
          ↓
Use weights to combine Values
          ↓
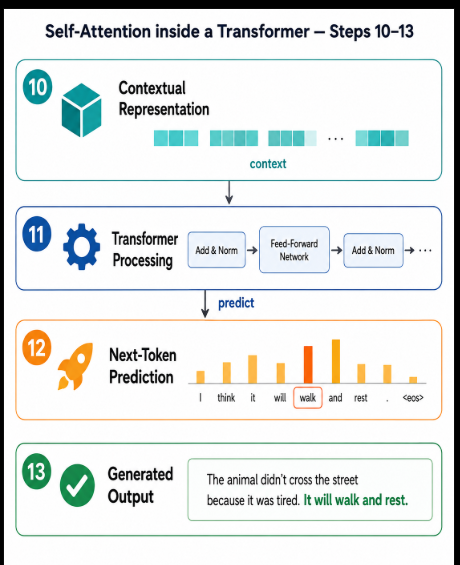
Contextual representation for "it"
          ↓
Continue through Transformer layer(s)
This is the application-engineer interpretation of scaled dot-product attention from the Transformer architecture; you do not need to derive its matrix equation now.
Step 1 — Input representation
The model isn't operating directly on English strings like:
"animal"
At the attention layer, it operates on numerical representations.
You'll study those representations more deeply when you reach Tokens and Embeddings.
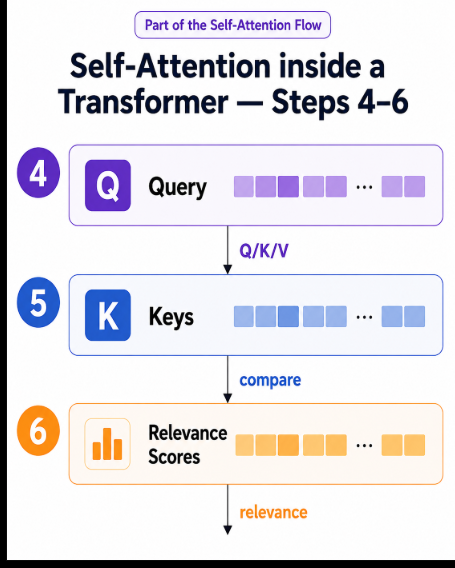
Step 2 — Query
Simple meaning:
What information am I looking for?
For our mental model:
"it"
 ↓
Query
 ↓
Which existing information is relevant to interpreting me?
Step 3 — Keys
Simple meaning:
What kind of information does each available token offer for matching?
Think:
animal → Key
street → Key
cross  → Key
tired  → Key
The Query is compared with these Keys.
Step 4 — Relevance score
Conceptually:
Query("it") ↔ Key("animal") = strong match
Query("it") ↔ Key("street") = weaker match
These are numerical relationships, not human-written labels.
Step 5 — Attention weights
Scores are normalized so information can be weighted.
Conceptually:
animal     █████████
street     ██
because    █
tired      ████
Important: those bars are only a conceptual illustration, not real model values.
Step 6 — Values
Simple meaning:
What information should actually be contributed if this token is relevant?
Keys answer:
Should I look here?
Values answer:
What information do I take from here?
Step 7 — Weighted combination
Conceptually:
animal information × high weight
+
tired information × useful weight
+
street information × low weight
+

             ↓
new contextual representation
Step 8 — Contextual representation
Now "it" is not represented in isolation.
It has absorbed useful contextual information.
Initial representation:
"it"


        ↓ Attention


Contextual representation:
"it" interpreted in relationship
to the relevant preceding context
Important Components / Subconcepts
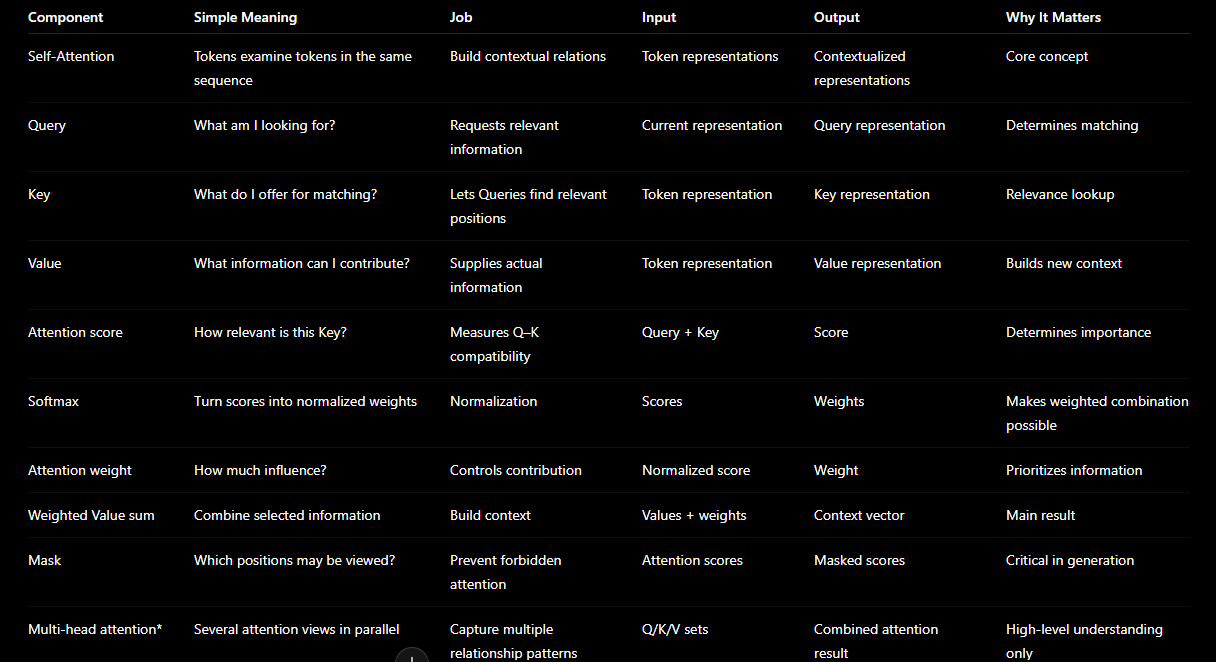
How they work together
Token representations
      │
      ├──→ Query
      ├──→ Key
      └──→ Value
              ↓
Query ↔ Keys
      ↓
Scores
      ↓
Weights
      ↓
Weights × Values
      ↓
Combined information
      ↓
Contextual representation
- One Simple Real-World Example
Let's use vehicle rental.
Input:
"The customer rented the Honda City because it was affordable."
Question:
What does "it" refer to?
Step 1
User/Input
"The customer rented the Honda City because it was affordable."
Step 2
Attention relationships conceptually consider:
"it"
 ↓
customer?
 ↓
rented?
 ↓
Honda City?
 ↓
affordable?
Step 3
Relevant relationships emerge:
it
 ↓ strong contextual relationship
Honda City
Step 4
Information is combined:
Honda City
+
rented
+
affordable
       ↓
context
Result
"it" → Honda City
Complete mental flow:
User sentence
     ↓
Token representations
     ↓
ATTENTION
     ↓
Relevant token relationships
     ↓
Contextual representations
     ↓
LLM can generate:
"It refers to the Honda City."
One Agentic AI Example
Later you build:
Hospital Booking Agent
User:
"Find a cardiologist in Delhi available tomorrow
and book the cheapest available appointment."
Architecture:
User Request
     ↓
LLM
     ↓
┌───────────────────────────────────┐
│ Transformer internal processing   │
│                                   │
│ ATTENTION                         │
│ relates:                          │
│ cardiologist ↔ find               │
│ Delhi ↔ location                  │
│ tomorrow ↔ availability           │
│ cheapest ↔ appointment options    │
└───────────────────────────────────┘
     ↓
LLM produces tool-call decision
     ↓
search_doctors(...)
     ↓
Hospital / Doctor API
     ↓
Available doctors
     ↓
LLM processes tool result
     ↓
choose/book according to workflow
     ↓
Final Response
This part IS handled partly by Attention
Inside the LLM:
Understanding contextual relationships
between the tokens/information
For example:
tomorrow → appointment availability
Delhi → doctor's location
cheapest → comparison requirement
This part is NOT handled by Attention
❌ Executing APIs
❌ Reading your database by itself
❌ Making HTTP requests
❌ Persisting agent state
❌ Long-term memory storage
❌ Authentication
❌ Workflow orchestration
❌ MCP connectivity
❌ Actually booking the appointment
Those are application/agent-system responsibilities.
The roadmap later introduces tool calling, APIs, RAG, agent loops, LangGraph state, memory, and MCP as separate layers for exactly this reason.
Compare with Closely Related Concepts
Attention vs Self-Attention
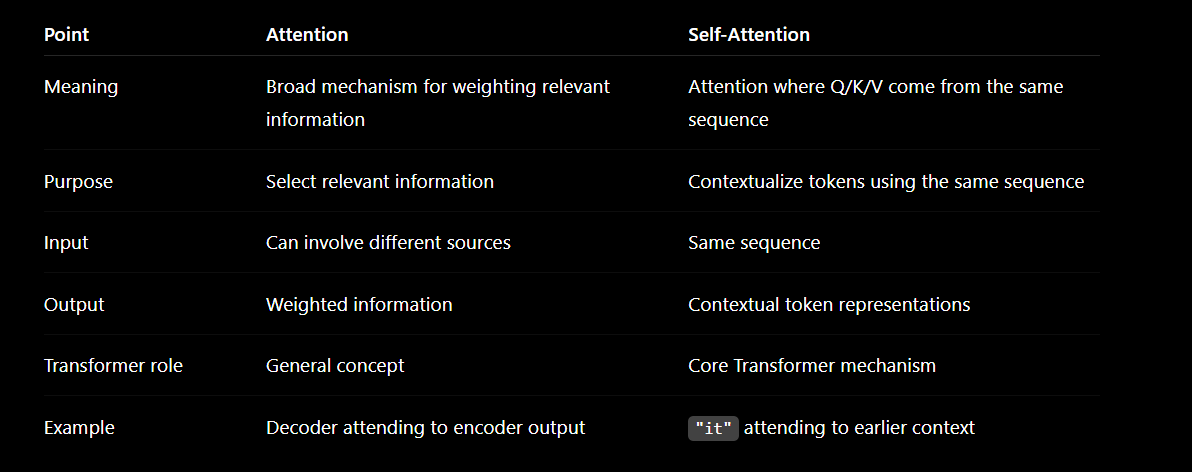
Important
Attention ≠ Self-Attention
Instead:
Self-Attention
      ⊂
Attention mechanisms
10.2 Attention vs Transformer
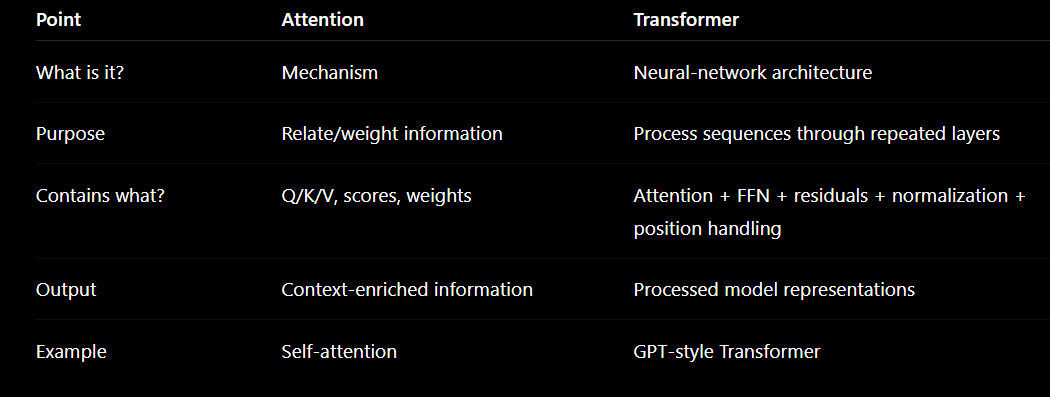
The reference blog explicitly warns:
Transformer ≠ Attention
Attention is a central mechanism inside Transformer blocks alongside feed-forward layers, normalization, residual connections, and positional information.
10.3 Attention vs Contextual Representation
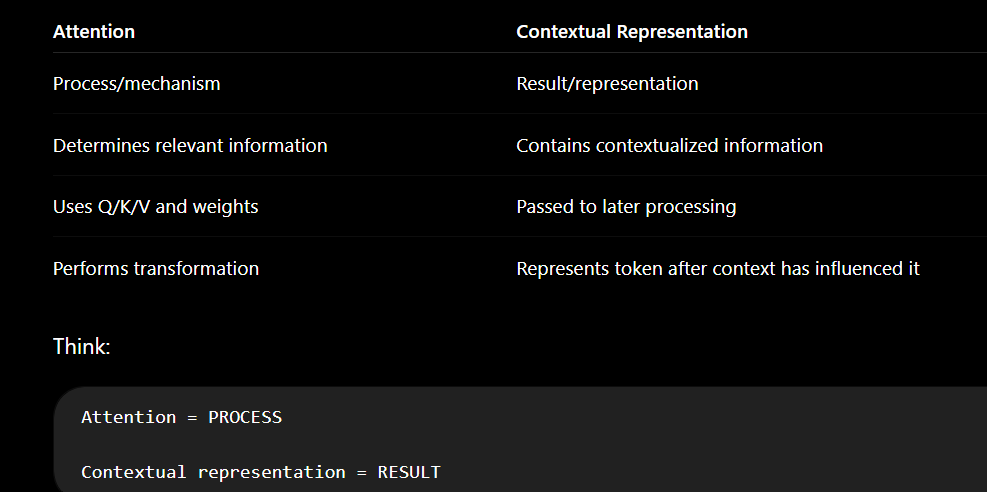
apple
+
released / phone
     ↓ Attention
Apple-the-company contextual representation
10.4 Attention vs Embedding
At your current stage:
Embedding/representation
     ↓
information enters Attention
     ↓
Attention mixes relevant contextual information
     ↓
contextual representation
Do not deeply study embeddings yet.
That is Step 4 in your roadmap.
Relationship with Previous and Next Concepts
Previous → Current → Next
Transformer
     ↓
provides the architecture containing
attention mechanisms
     ↓
ATTENTION
     ↓
explains how representations exchange
context-relevant information
     ↓
Tokens / Tokenization
What should I already know?
Before Attention, you should know:
Transformer = architecture.
Transformer ≠ LLM.
Transformer ≠ Attention.
Basic idea of contextual representation.
Encoder vs Decoder at high level.
Next-token generation at high level.
Minimum Neural Network/Deep Learning idea.
The reference blog establishes those concepts before explicitly pointing to Attention as the next step.
What becomes easier after Attention?
You will understand:
Why context matters.
Why the same token can behave differently in different sentences.
Why prompt wording matters.
Why distant context can influence generation.
How Transformer representations become contextual.
Why ambiguous prompts are dangerous.
Why LLMs are sensitive to irrelevant context.
Which future Agentic AI concepts benefit from this knowledge?
Attention
   ↓
LLM behavior
   ↓
Prompt Engineering
   ↓
Context management
   ↓
RAG
   ↓
Tool descriptions
   ↓
Tool selection
   ↓
Agent reasoning behavior
   ↓
Memory/context design
   ↓
Multi-agent message design
Important: learning order ≠ runtime order
Your roadmap teaches:
Transformer
→ Attention
→ Tokens
→ Embeddings
But actual inference processing is conceptually closer to:
Text
→ Tokenization
→ token representations
→ Transformer layers
→ Attention
→ contextual representations
→ prediction
The roadmap order is pedagogical, not the literal runtime ordering.
What Should I NOT Learn Now?
This is one of the most important sections.
❌ Full attention matrix calculations
Reason: You only need Q/K/V conceptually.

Learn it later when: You specifically study Transformer implementation or ML engineering.
❌ Q × Kᵀ derivations
Reason: Knowing the purpose of Q–K matching is enough now.

Learn it later when: You need low-level architecture knowledge.
❌ Matrix calculus
Reason: Not needed to build LLM applications or agents.

Learn it later when: Moving toward model research/training.
❌ Backpropagation through Attention
Reason: This explains training, not application-time agent engineering.

Learn it later when: Training/fine-tuning models at low level.
❌ Implementing Self-Attention from scratch
Reason: Your agent will normally consume a trained LLM.

Learn it later when: Learning PyTorch model internals.
❌ CUDA/GPU Attention kernels
Reason: Infrastructure specialization, not foundational Agentic AI.

Learn it later when: Building inference engines.
❌ FlashAttention implementation
Reason: Optimization topic rather than conceptual Attention.

Learn it later when: Optimizing model serving.
❌ Sparse/Linear Attention research
Reason: Solves scaling problems beyond your current project.

Learn it later when: Evaluating long-context architectures.
❌ Studying every attention variant
Examples:
Multi-query attention
Grouped-query attention
Linear attention
Local attention
Global attention
Sparse attention
Windowed attention
Reason: Framework/architecture overload.
Learn later when: A production model choice requires understanding the trade-off.
This matches the roadmap's explicit instruction to avoid attention calculations, Transformer mathematics, backpropagation, model training, and low-level model implementation during Project 0.
Practical Experiments
Your roadmap specifically proposes an Attention Concept Demo using same-word/different-context examples and says that calculating attention matrices is unnecessary.
Experiment 1 — Same Token, Different Context
Goal
Observe context-dependent interpretation.
Input
A. The bank approved my loan.
B. The fisherman sat on the bank.
What I Should Do
Ask an LLM:
What does "bank" mean?
Which parts of the sentence helped determine its meaning?
Expected Output
A:
bank → financial institution
loan → important contextual clue
B:
bank → side of a river
fisherman/sat → contextual clues
What Concept It Proves
same token/text
+
different context
↓
different contextual interpretation
What I Should Observe
Attention is about relationships, not dictionary lookup alone.
Common Mistake
Thinking:
bank has one fixed contextual representation.
Experiment 2 — Pronoun Relationship
Goal
See long-distance dependency.
Input
The animal didn't cross the street because it was tired.
Ask
What does "it" most likely refer to?
What evidence from the sentence supports that?
Expected Output
it → animal
Concept It Proves
A later token can depend on information associated with an earlier token.
Observe
Distance alone does not determine relevance.
Common Mistake
Thinking Attention only considers immediately neighboring words.
Experiment 3 — Remove Important Context
Goal
Observe what happens when supporting context disappears.
Input A
The bank approved my mortgage application.
Input B
I went to the bank.

Ask the same question:

What kind of bank does this mean?
Expected
A:

strong financial interpretation

B:

more uncertain without additional context
Concept It Proves
Less useful context
        ↓
less evidence for interpretation
Common Mistake
Assuming an LLM always possesses enough evidence to resolve ambiguity.
Experiment 4 — Relevant vs Distracting Context
Goal
See how additional information can complicate interpretation.
Compare:
Patient needs a cardiologist in Delhi tomorrow.
with:
Patient needs a cardiologist.
The hospital was founded in 1998.
Delhi has several tourist attractions.
Tomorrow is Tuesday.
The patient needs an appointment in Delhi tomorrow.
Ask:
Extract specialty, location and appointment date.
Observe
The model must distinguish task-relevant information from distracting context.
Agentic lesson
Later in RAG:
retrieving more documents
≠
automatically better answers
You want relevant context, not simply maximum context.
- Debugging / Failure Experiment
Use:
Normal Input
↓
"The doctor told Ravi that his appointment was cancelled."


Expected
↓
"his" likely relates to Ravi
Now:
Bad / Ambiguous Input
↓
"John told David that he had been selected."
Ask:
Who was selected?
Potential result:
John?
or
David?
Why?
Because the sentence itself is ambiguous.
Attention
≠
missing-information detector that can
always discover one objectively correct answer
Attention can model relationships among available information.
It cannot make an under-specified sentence magically contain information that isn't there.
Mental model:
Bad/ambiguous context
        ↓
Attention still operates
        ↓
multiple plausible relationships
        ↓
uncertain model behavior
This is why your previous reference blog correctly notes that contextual processing does not equal perfect human understanding.
15.
Code Only When It Helps Learning
For this specific roadmap step, I do not recommend coding Attention from scratch.
Your highest-value experiment is:
Input sentence
     ↓
LLM
     ↓
change context
     ↓
compare interpretation
     ↓
explain why behavior changed
The roadmap explicitly says you do not need to calculate attention matrices and that Project 0 should use an LLM while explaining the underlying mechanism conceptually.
So for now:
❌ PyTorch self-attention implementation
❌ NumPy Q/K/V matrix multiplication
❌ custom softmax implementation
✅ Context experiments
✅ Ambiguity experiments
✅ Compare outputs
✅ Explain Q/K/V verbally
When you eventually study model internals, writing a small attention implementation can become useful.
Architecture Diagrams
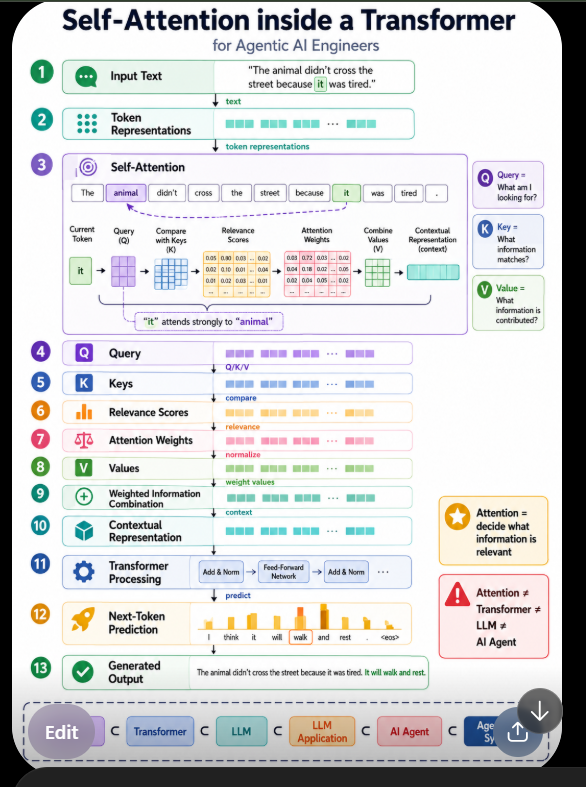
16.1 Diagram A — End-to-End Pipeline
┌─────────────────────────┐
│       Input Text        │
│ "The animal ... it..."  │
└────────────┬────────────┘
             │ text → tokens/representations
             ↓
┌─────────────────────────┐
│  Token Representations  │
└────────────┬────────────┘
             │ representations enter Transformer
             ↓
┌─────────────────────────┐
│      SELF-ATTENTION     │
└────────────┬────────────┘
             │ relevant information is combined
             ↓
┌─────────────────────────┐
│ Contextual              │
│ Representations         │
└────────────┬────────────┘
             │ processed by later layers
             ↓
┌─────────────────────────┐
│ Next-Token Prediction   │
└────────────┬────────────┘
             │ predicted token
             ↓
┌─────────────────────────┐
│ Generated Output        │
└─────────────────────────┘
The Transformer reference blog already establishes the outer Text → Tokens → Transformer → Contextual Representation → Next-token Prediction pipeline; Attention is the contextual-processing box we are opening in this lesson.
16.2 Diagram B — Internal Anatomy
 ┌──────────────── SELF-ATTENTION ────────────────┐
             │                                                │
Token        │      ┌──────── QUERY ────────┐                 │
representations ───→│ What am I looking for?│                 │
             │      └──────────┬────────────┘                 │
             │                 │ compare                      │
             │                 ↓                              │
             │      ┌───────────────────────┐                 │
             │      │        KEYS           │                 │
             │      │ What can each offer?  │                 │
             │      └──────────┬────────────┘                 │
             │                 │ relevance scores             │
             │                 ↓                              │
             │      ┌───────────────────────┐                 │
             │      │ Attention Weights     │                 │
             │      └──────────┬────────────┘                 │
             │                 │ weight                       │
             │                 ↓                              │
             │      ┌───────────────────────┐                 │
             │      │       VALUES          │                 │
             │      │ Actual information    │                 │
             │      └──────────┬────────────┘                 │
             │                 │ weighted combination         │
             │                 ↓                              │
             │      ┌───────────────────────┐                 │
             │      │ Contextual            │                 │
             │      │ Representation        │                 │
             │      └───────────────────────┘                 │
             └────────────────────────────────────────────────┘


                         ↓
                  Transformer layer


                         ↓
                another Transformer layer


                         ↓
                      repeat
At generation time, this processing repeats as the model produces subsequent tokens, while causal attention prevents a position from accessing future generated tokens. The central Q/K/V attention mechanism comes directly from the Transformer architecture.
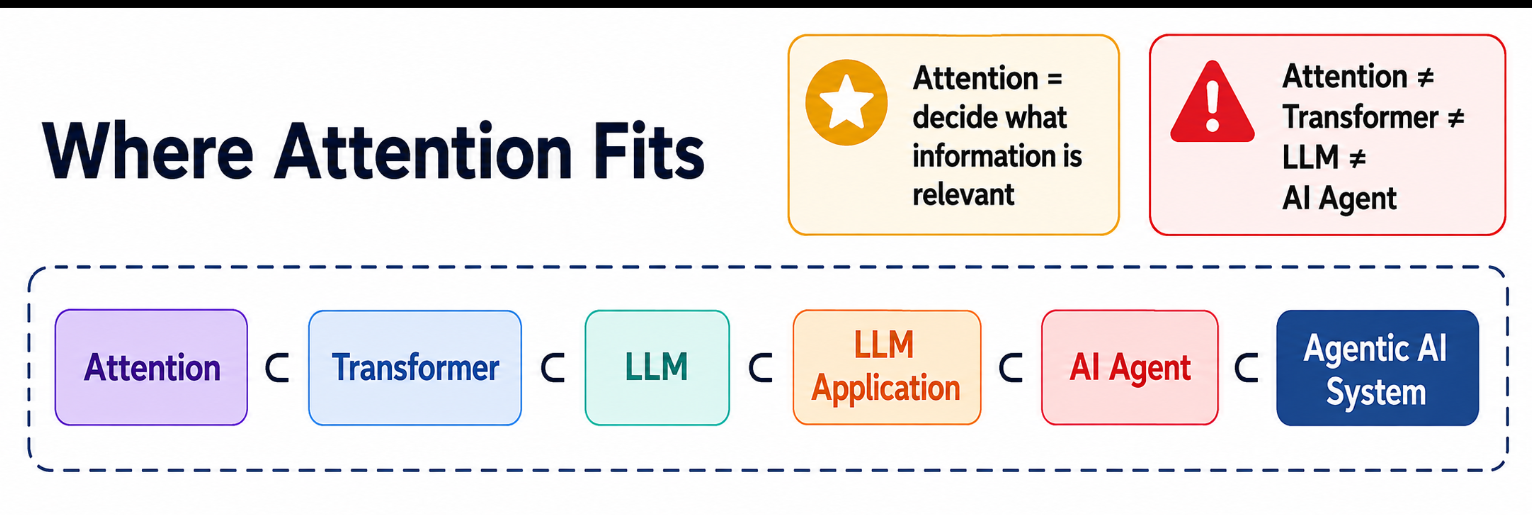
16.3 Diagram C — Ecosystem Hierarchy
Attention
    ⊂
Transformer Block / Layer
    ⊂
Transformer-based LLM
    ⊂
LLM Application
    ⊂
AI Agent
    ⊂
Agentic AI System
What each outer layer adds:
Attention
→ contextual information exchange


Transformer
→ attention + FFN + residuals + normalization + repeated processing


LLM
→ trained language capabilities


LLM Application
→ prompts + API + application logic


AI Agent
→ tools + decisions/actions + iterative loop


Agentic AI System
→ state + memory + workflows + guardrails
  + orchestration + human oversight + production infrastructure
The reference blog uses the same hierarchy from Transformer → LLM → application → tools → Agent → Agentic AI.
Mental Model
Attention = "For this token, what other information should matter, and how much?"
Memorize:
Current token representation
        ↓
What do I need?
        ↓
QUERY
        ↓
Where is relevant information?
        ↓
KEYS
        ↓
How relevant?
        ↓
ATTENTION WEIGHTS
        ↓
What information should I take?
        ↓
VALUES
        ↓
Combine useful information
        ↓
CONTEXTUAL REPRESENTATION
Even shorter:
Look
 ↓
Match
 ↓
Weight
 ↓
Combine
 ↓
Understand in context
- Common Misunderstandings ❌ Attention = Transformer ✅ Correct
Attention is one mechanism inside a Transformer.
Transformer
├── Attention
├── Feed-forward network
├── Residual connections
├── Normalization
└── Position information
The reference blog explicitly makes this distinction.
❌ Attention = LLM
✅ Correct
Attention
  ↓ inside
Transformer
  ↓ architecture used by
LLM
❌ Attention understands English words directly
✅ Correct
Attention operates on numerical token representations.
❌ Self-attention only looks at nearby words
✅ Correct
A token may interact with distant permitted tokens too.
❌ Query is the user's question
✅ Correct
In Q/K/V terminology, Query is an internal learned representation associated with a token/position.
It is not simply:
User's API query
This distinction is extremely important.
❌ Key = database key
✅ Correct
In Attention, Key means an internal representation used for relevance matching.
Not:
primary key
API key
Redis key
❌ Value = actual word/value string
✅ Correct
Value is another learned numerical representation carrying information to be combined.
❌ Attention weights are database search scores
✅ Correct
They are internal model weights used while computing contextual representations.
❌ Attention = retrieval
✅ Correct
RAG retrieval might do:
query
 ↓
vector DB
 ↓
documents
Attention happens inside the model over representations in its allowed context.
Retrieval ≠ Attention
But retrieved text can become context that the model subsequently processes using Attention.
❌ More context always makes Attention work better
✅ Correct
Irrelevant, conflicting, or ambiguous context can still produce poor model behavior.
❌ Attention means the LLM has memory
✅ Correct
Attention ≠ long-term memory

Attention processes available context.
Agent memory is an application/system-level capability.
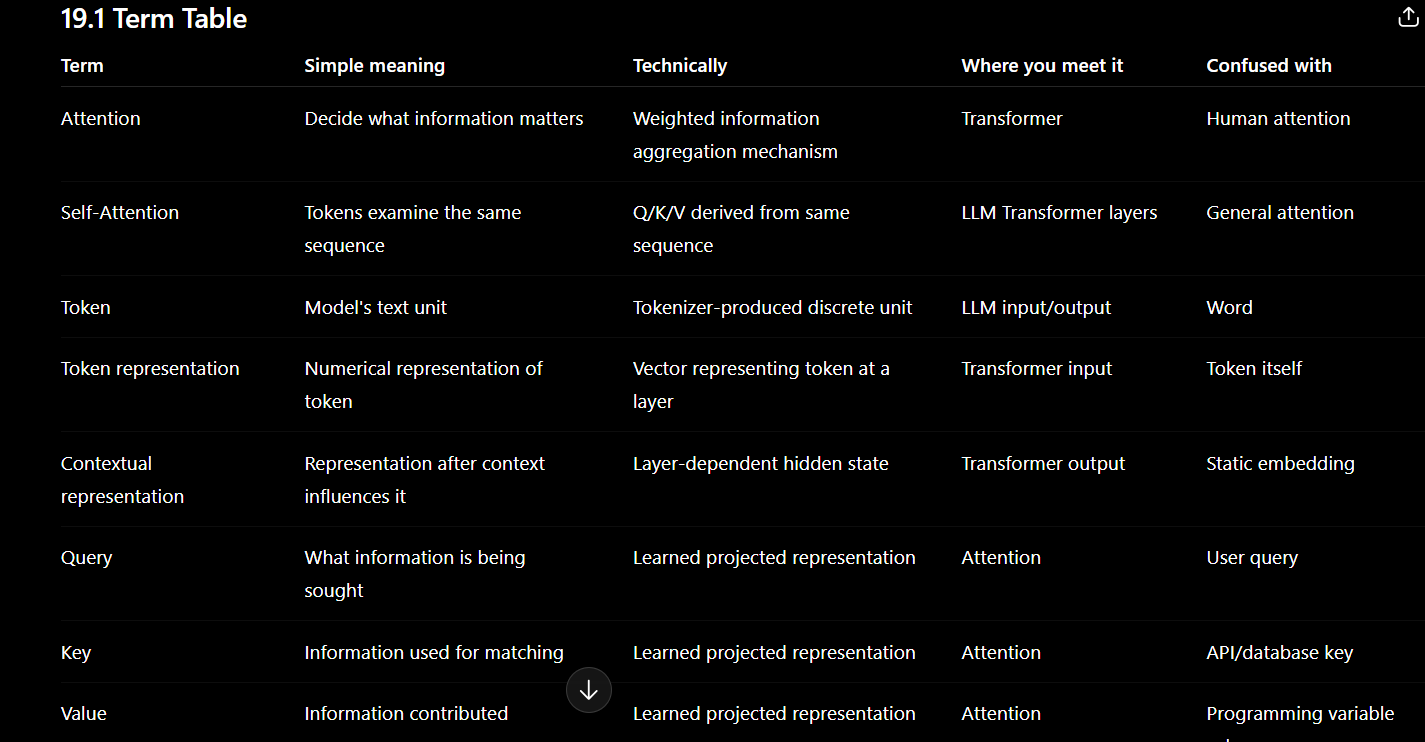
Important Terminology
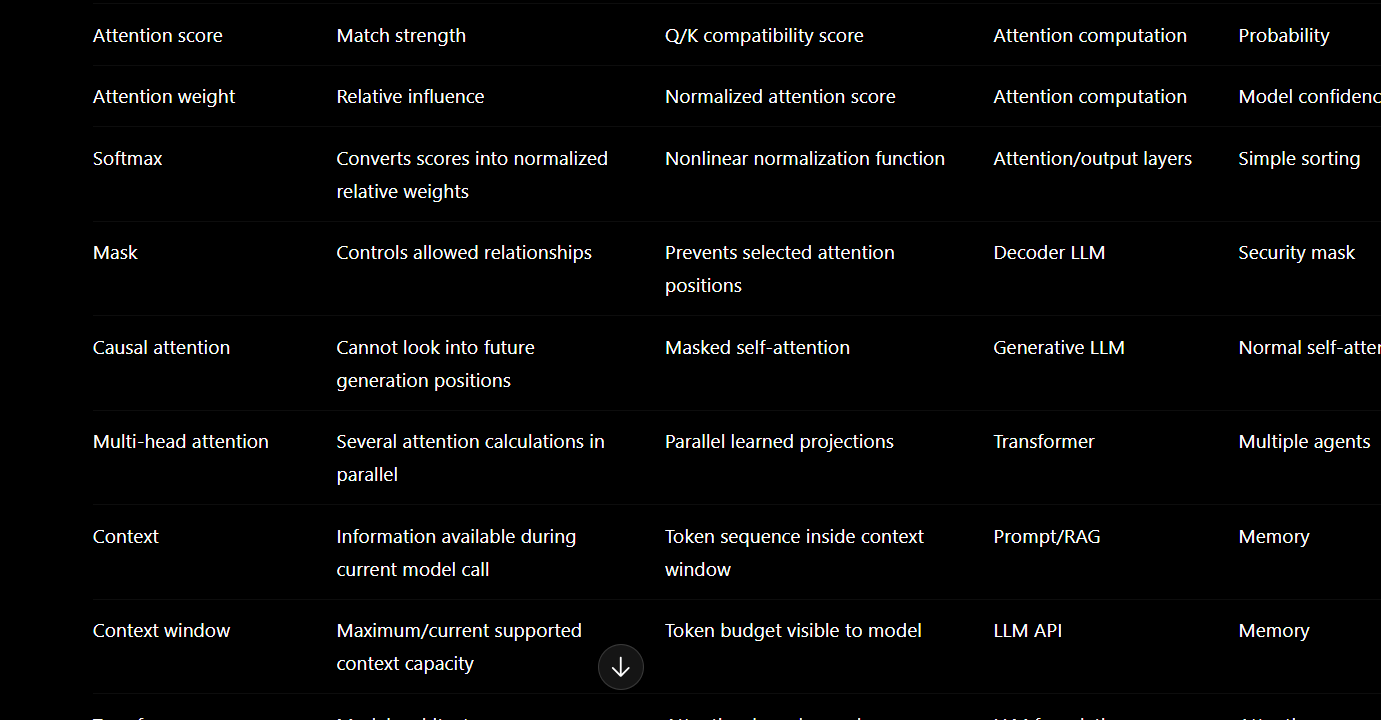
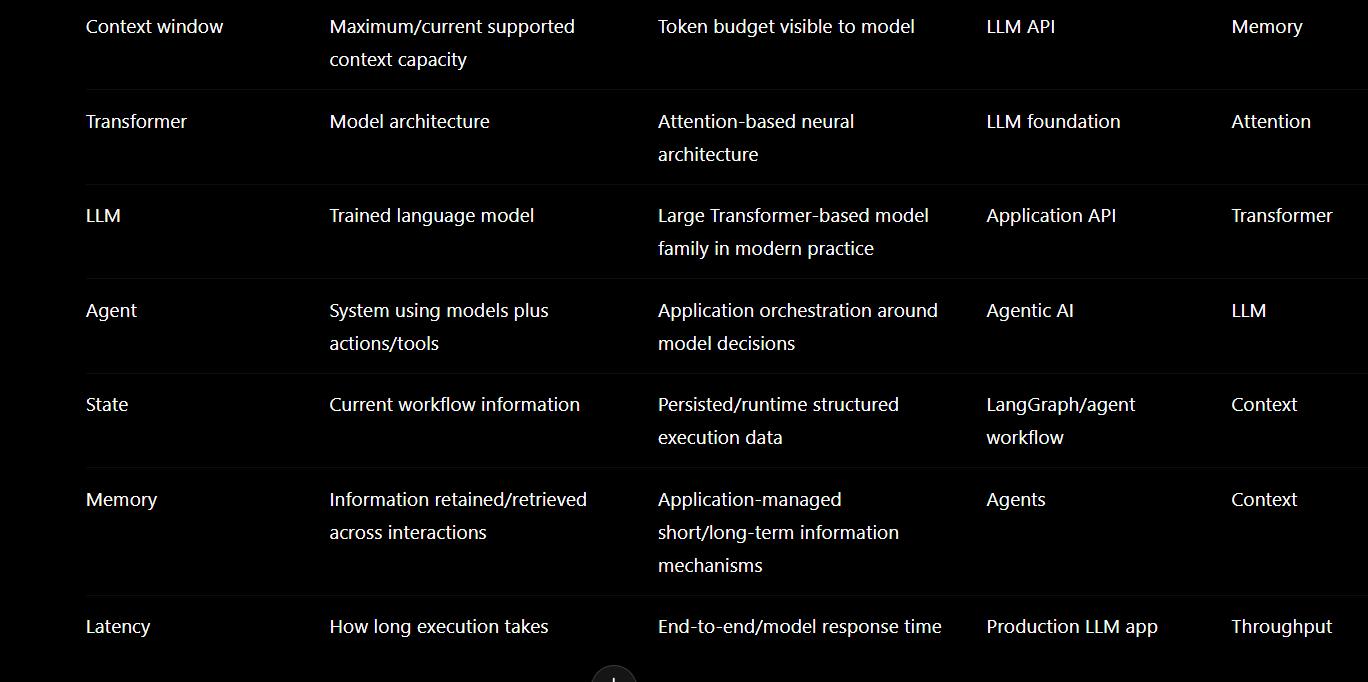
19.
Contrast Pairs
Token vs Word
Token = unit processed by model/tokenizer.
Word = human linguistic unit.
Difference: one word may produce one or several tokens.
Example:
"Agentic"
might be split differently depending on tokenizer.
What breaks if confused: cost/context calculations become wrong.
You'll study this fully in Step 3. The roadmap specifically postpones it until after Attention.
Token Representation vs Contextual Representation
Token representation
=
initial/intermediate numerical information
for a token


Contextual representation
=
representation after information from context
has influenced it through Transformer processing
Example:
"Apple"
Before rich context:
Apple representation
After:
Apple released the new phone
                ↓
Apple → company-related contextual representation
The reference blog already establishes this distinction conceptually.
Query vs Key
Query = What am I looking for?


Key = What do I contain that can match?
Difference:
Query asks; Key enables matching.
Example:
Query("it")
     ↕
Key("animal")
What breaks if confused:
You lose the central intuition behind self-attention.
Key vs Value
Key
=
used to determine relevance


Value
=
information that is actually contributed
Analogy:
Key → label on a drawer
Value → useful information inside drawer
Not mathematically exact, but excellent for your current level.
Attention Score vs Attention Weight
Score
=
raw relevance signal


Weight
=
normalized relative influence
Conceptually:
Scores
 ↓
normalization
 ↓
Weights
Attention vs Self-Attention
Attention
=
general mechanism
Self-Attention
=
Q/K/V operate over the same sequence
Attention vs Transformer
Attention = mechanism
Transformer = architecture containing attention
Confusing them means you mistake a component for the entire system.
Transformer vs LLM vs AI Agent
Transformer
=
architecture


LLM
=
trained language model built using Transformer-style architecture


AI Agent
=
application/system that uses an LLM plus tools/actions/logic
The reference blog explicitly uses this hierarchy.
Prompt vs Context
Prompt
=
instructions/input you provide


Context
=
all information currently available to the model
for that inference
Prompt contributes to context, but:
Prompt ≠ entire context
Context vs Memory vs State
Context
=
information available to the LLM right now


Memory
=
information intentionally retained/retrieved
across interactions


State
=
current structured information about
an application's/workflow's execution
Example agent:
Context:
current conversation + RAG documents


Memory:
patient's saved preferences


State:
appointment_search_completed = true
Retrieval vs Attention
Retrieval
=
find external/relevant information


Attention
=
internally combine relevant information
already available to model processing
Together:
Vector DB
 ↓ Retrieval
Relevant documents
 ↓ added to prompt/context
LLM
 ↓ Attention
Contextual processing
 ↓
Answer
19.3
Terms You Must Be Able to Use
- Self-Attention
"The LLM uses self-attention internally to build context-dependent representations from the tokens available to it."
- Query
"In attention terminology, Query is an internal representation used to find relevant information; it isn't the same thing as the user's search query."
- Key
"The Query is compared against Keys to determine which positions are relevant."
- Value
"Attention weights determine how strongly the corresponding Value information contributes to the result."
- Attention Weight
"Attention weights control the relative contribution of information during the attention operation."
- Contextual Representation
"After Transformer processing, the token representation contains information influenced by its context."
- Causal Mask
"A generative decoder uses causal masking so the current position cannot use future tokens."
- Context
"I want the RAG pipeline to provide highly relevant context instead of simply filling the entire context window."
Interview Question
s
20.1
Subjective / Explain-It Questions
Q1. What is Attention in one sentence? ⭐
Model answer:
Attention is a mechanism that lets a token determine which available information is relevant and combine that information to build a context-dependent representation.
Follow-up they'll ask:
Why is that useful?
Red flag answer:
"Attention means the AI concentrates like a human."
Why wrong: that is an analogy, not the technical mechanism.
Q2. Why do Transformers need Attention? ⭐⭐
Model answer:
A token's meaning often depends on other tokens. Attention gives the Transformer a way to model those relationships directly and combine relevant information when constructing contextual representations.
Follow-up:
Give me an example.
Good example:
The animal didn't cross the street because it was tired.
"it" depends on earlier context.
Q3. What is Self-Attention? ⭐⭐
Model answer:
Self-attention means the model computes relationships among representations within the same sequence. Each position can use relevant information from other allowed positions to update its own representation.
Follow-up:
How is that different from general attention?
Red flag:
"Self-attention means the model thinks about itself."
Wrong because "self" refers to the same sequence, not introspection.
Q4. Explain Query, Key and Value without mathematics. ⭐⭐⭐
Model answer:
I use this mental model: Query means "what information am I looking for?", Key means "what information can I match against?", and Value means "what information will actually be contributed?" The Query–Key relationship determines weights, which are then used to combine Values.
Follow-up:
Is Query the user's prompt?
Answer:
No. Q in Q/K/V is an internal representation.
Q5. What is an attention weight? ⭐⭐⭐
Model answer:
It represents relative influence in an attention operation. After relevance scores are normalized, the resulting weights control how strongly Value information from different positions contributes to the contextual result.
Follow-up:
Does the highest attention weight always prove what the model "reasoned about"?
Answer:
No. Treating raw attention weights as a complete human-readable explanation of model reasoning is too strong.
Q6. How does Attention create contextual representations? ⭐⭐⭐
Model answer:
The current representation produces a Query, available positions provide Keys and Values, Query–Key comparisons produce relevance scores, the scores become weights, and those weights combine Value information. The result contains information influenced by context.
Follow-up:
Does that happen only once?
Answer:
No. Transformer layers repeat contextual processing.
Q7. Attention vs Transformer—what is the difference? ⭐⭐⭐
Model answer:
Attention is a mechanism. Transformer is the larger architecture that contains attention together with components such as feed-forward networks, residual connections, normalization, and position information. So Attention is a part, not the whole architecture.
Follow-up:
Then is an LLM a Transformer?
Answer:
An LLM is a trained model; modern LLMs commonly use Transformer-based architectures.
Q8. Why was the Attention-based Transformer important compared with recurrent models? ⭐⭐⭐
Model answer:
Recurrent architectures process sequences through recurrent state step by step. Transformers use attention to create direct relationships among positions and remove recurrence, which also enables far more parallel computation during training. That made the architecture much more scalable for large sequence models.
Follow-up:
Does that mean RNNs are useless?
Answer:
No. It means Transformers became dominant for many modern language-modeling workloads; it does not mean recurrence is universally useless.
Q9. What is causal/masked self-attention? ⭐⭐⭐⭐
Model answer:
In autoregressive generation, a token cannot use information from future tokens that haven't been generated yet. A causal mask restricts attention so each generation position only uses permitted earlier/current context.
Follow-up:
Why is that necessary?
Answer:
Otherwise training/generation could leak information from the future.
Q10. Does understanding Attention mean an Agentic AI engineer must implement it from scratch? ⭐⭐⭐⭐
Model answer:
No. My responsibility is usually to use trained LLMs effectively and understand enough internals to diagnose prompt/context/model behavior. I need conceptual knowledge of self-attention, Q/K/V and context, not a custom CUDA or PyTorch implementation.
Follow-up:
When would you go deeper?
Answer:
If I move into model training, architecture research, or inference-engine optimization.
Q11. You're building a RAG agent and quality gets worse when you add more retrieved documents. How can your Attention knowledge help debug it? ⭐⭐⭐⭐
Model answer:
I would first suspect context quality, not assume more text is better. Irrelevant or conflicting chunks become additional information the model must process. I'd inspect retrieval relevance, chunking, ordering, duplication, and context size before changing the agent framework.
Follow-up:
Is Attention itself the retriever?
Answer:
No. Retrieval happens outside the model; Attention processes the context that retrieval supplies.
Q12. A hospital agent interprets "Book Dr. Sharma's earliest appointment after Tuesday" incorrectly. Which stages would you inspect? ⭐⭐⭐⭐⭐
Model answer:
I'd separate model interpretation from application logic. First test whether the LLM consistently relates "earliest", "after Tuesday", and "Dr. Sharma" correctly in isolation. Then inspect prompt/context quality, tool schema, generated arguments, tool execution, and returned data. Attention is internal to the interpretation stage; it isn't responsible for API execution.
Follow-up:
Why is that separation important?
Answer:
Otherwise I'd incorrectly blame "the model" for a bug in tool schema, date handling, state, or backend code.
Objective / MCQs
Q1. Which best describes Attention? ⭐
A) A vector database search algorithm
B) A mechanism that weights relevant information when building representations
C) Long-term memory for an AI agent
D) An API-calling framework
Answer: B
Why others are wrong:
A: Retrieval ≠ Attention.
C: Memory ≠ Attention.
D: Tool calling ≠ Attention.
Q2. In the Q/K/V mental model, Query means: ⭐⭐
A) The HTTP query parameter
B) The user's full prompt
C) An internal representation of what information is being sought
D) A database SELECT statement
Answer: C
A/B/D misuse normal software meanings of "query".
Q3. What is the best distinction between Key and Value? ⭐⭐⭐
A) They are identical names for the same thing
B) Key participates in relevance matching; Value carries information to be combined
C) Key is a database key; Value is a database column
D) Value decides relevance while Key stores memory
Answer: B
C is the common software-engineering terminology trap.
Q4. Which statement is correct? ⭐⭐⭐
A) Attention = Transformer
B) Transformer = AI Agent
C) Attention is a mechanism inside Transformer architectures
D) AI Agent = Attention + Tokens
Answer: C
A: part ≠ whole.
B: architecture ≠ application agent.
D: agents require application-level capabilities such as tools/workflow/state.
Q5. Which is handled directly by an Agent application's tool layer rather than Attention? ⭐⭐⭐
A) Combining contextual token information
B) Computing internal token relationships
C) Executing search_doctors() against an API
D) Contextualizing "tomorrow" relative to the request
Answer: C
Tool execution is application logic.
Q6.** What should you learn NOW according to this roadmap?** ⭐⭐⭐
A) CUDA FlashAttention kernels
B) Q/K/V matrix derivations
C) Self-attention, high-level Q/K/V, weights and context dependence
D) Train GPT from scratch
Answer: C
The roadmap explicitly defines C as Step 2 and explicitly postpones the mathematical/implementation depth represented by the other options.
Question
"Explain how self-attention converts a token representation into a context-dependent representation, and tell me where that mechanism stops and the Agent application begins."
Your under-60-second answer
Self-attention lets each token use information from other allowed tokens in the sequence. Conceptually, each representation produces a Query, Key, and Value. The Query is matched against Keys to determine relevance, those scores become attention weights, and the weights combine Value information. That produces a context-dependent representation, and Transformer layers repeat this processing. This happens internally inside the LLM. It does not execute APIs, retrieve databases, maintain agent memory, or orchestrate workflows—those capabilities belong to the application or Agent layer


Top comments (0)