
Where This Concept Fits
Concepts Covered
What Theory Should I Learn?
Explain the Concept in Increasing Depth
Why Was Tokenization Needed?
Complete Internal Working Flow
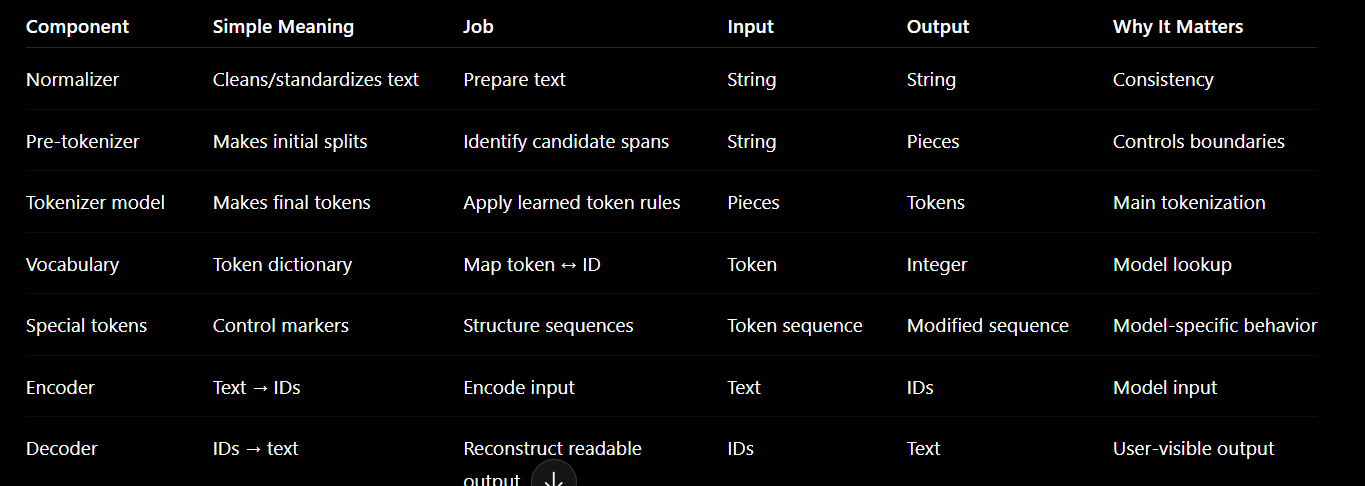
Important Components / Subconcepts
One Agentic AI Example
Compare with Closely Related Concepts
Relationship with Previous and Next Concepts
What Should I NOT Learn Now?
Practical Experiments
Code Only When It Helps Learning
Architecture Diagrams
Mental Model
Common Misunderstandings
Important Terminology
Contrast Pairs
Terms You Should Be Able to Use Naturally
Interview Questions
Subjective Questions
Objective Questions
Where This Concept Fits
Transformer + Attention
        ↓
understand how tokens interact
        ↓
TOKENS / TOKENIZATION
        ↓
convert text into model-readable units
        ↓
Embeddings
        ↓
convert token IDs into vectors
        ↓
Transformer processing
        ↓
LLM Applications
        ↓
RAG + Tools + Memory + State
        ↓
AI Agents
        ↓
Production Agentic AI
Why learn Tokens now?
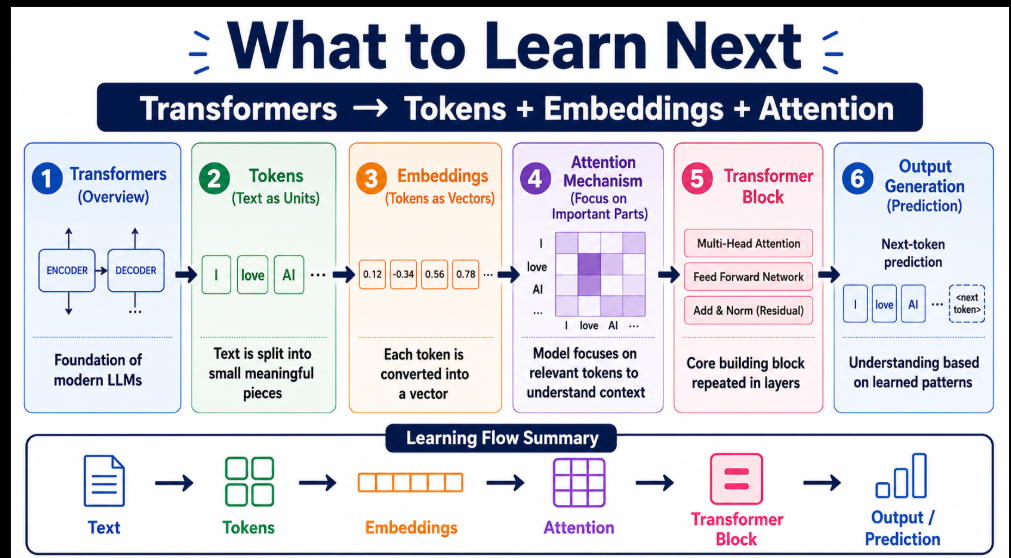
You already need the mental model that Transformers operate on sequences. But the Transformer doesn't directly receive your English/Hindi sentence as text. A tokenizer converts that text into discrete units and corresponding IDs before the model processes them. Tokenizer pipelines can include normalization, pre-tokenization, a tokenization model and post-processing.
You need this concept before embeddings because:
Text
 ↓
Tokens
 ↓
Token IDs
 ↓
Embeddings
 ↓
Transformer
If you skip Tokens / Tokenization
Later you may struggle to understand:
why 1,000 words ≠ 1,000 tokens;
why two visually similar prompts can have different token counts;
why prompts hit context limits;
why long tool results make an agent expensive;
why chunks in RAG are often budgeted in tokens;
why truncation can silently remove important context;
what embeddings are actually embedding;
how next-token generation works;
why model latency and cost increase with larger contexts.
These are engineering concerns in production LLM applications, not merely NLP theory.
2.
Concepts Covered
Learning tree
Text
 ↓
Tokenization
 ↓
Tokens
 ↓
Vocabulary
 ↓
Token IDs
 ↓
Special Tokens
 ↓
Token Sequence
 ↓
Embeddings                ← Next Concept
 ↓
Contextual Representations
 ↓
Next-Token Prediction
 ↓
LLM
 ↓
AI Agent
Must Learn Now
Token
Tokenization
Tokenizer
Token vs word
Vocabulary
Token ID
Subword token
Basic idea of BPE
Encoding
Decoding
Special tokens
Token count
Context-window relationship
Truncation
Token budget
Why different tokenizers produce different token sequences
Learn at High Level
normalization;
pre-tokenization;
byte-level tokenization;
WordPiece;
Unigram;
padding;
tokenizer/model compatibility.
Hugging Face currently documents BPE, WordPiece, Unigram and WordLevel as tokenizer-model approaches, with normalization, pre-tokenization, model processing and post-processing forming the broader pipeline.
Learn Later
training a tokenizer;
custom vocabularies;
tokenizer optimization for multilingual models;
sophisticated chunk/token budgeting;
KV cache and token-processing performance;
detailed decoding/sampling behavior;
model-specific chat templates.
Do Not Learn Yet
tokenizer research papers;
implementing production BPE from scratch;
mathematical optimization of vocabulary;
GPU tokenizer kernels;
training foundation models;
deep Unicode internals.
What Theory Should I Learn?
Your requested balance is approximately 30% theory, 50% experiments, 20% debugging/comparison.
3.1 Token
Definition:
A token is one unit of text that a tokenizer represents for model processing.
It might correspond to:
word
subword
punctuation
space-related piece
character
byte sequence
depending on the tokenizer.
Why it exists: Models need discrete numerical inputs rather than arbitrary text strings.
Before: Pure word-level approaches require huge vocabularies and handle unseen words poorly.
How it works:
"booking confirmed"
       ↓
Tokenizer
       ↓
[token A, token B, token C...]
       ↓
IDs
Agentic importance: Token counts affect prompt size, retrieved context, tool observations, cost and latency.
3.2 Tokenization
Definition:
Tokenization is the process of converting text into token units that can be mapped to IDs.
Why: The Transformer cannot operate directly on arbitrary text.
How:
Raw text
  ↓
optional normalization
  ↓
pre-tokenization
  ↓
subword/tokenization algorithm
  ↓
tokens
  ↓
token IDs
This matches the tokenizer pipeline documented by Hugging Face.
3.3 Vocabulary
Definition:
The vocabulary is the tokenizer's known mapping of token pieces to numeric IDs.
Conceptually:
"book"   → 3812
"ing"    → 287
"car"    → 1421
The actual numbers depend entirely on the tokenizer.
Agentic relevance: You normally use the tokenizer paired with your chosen pretrained model rather than editing its vocabulary yourself.
3.4 Subword Tokenization
Suppose the tokenizer does not treat:
internationalization
as one token.
It might conceptually split it:
international
ization
This provides a useful middle ground between character-level and whole-word vocabularies. BPE, for example, progressively combines frequently occurring pieces and can represent unseen words using multiple subword tokens.
3.5 Token IDs
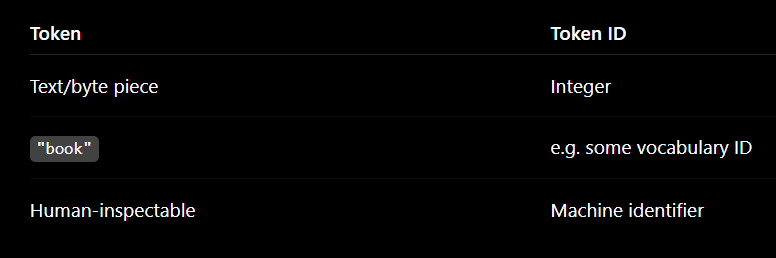
A token is the textual/byte piece.
A token ID is its numeric vocabulary identifier.
Text
"Book a hospital appointment"
            ↓
Tokens
["Book", " a", " hospital", " appointment"]
            ↓
IDs
[... integers ...]
Exact splits and IDs depend on the selected tokenizer. OpenAI's tiktoken, for example, exposes encode() for converting text into token IDs and decode() for converting them back.
Explain the Concept in Increasing Depth
Level 1 — One-Line Explanation
Tokenization converts human-readable text into small numbered pieces that an LLM can process.
Level 2 — Beginner Explanation
Imagine:
"I want to book a doctor"
The LLM cannot directly consume the sentence like a human.
First:
Sentence
   ↓
small pieces
   ↓
numbers
   ↓
LLM
Those pieces are tokens.
The conversion process is tokenization.
Level 3 — Developer Explanation
Think of the tokenizer as an input/output adapter:
string
 ↓
Tokenizer.encode()
 ↓
List[int]
 ↓
Embedding lookup
 ↓
Tensor/vector representations
 ↓
Transformer
And during output:
Predicted token IDs
 ↓
Tokenizer.decode()
 ↓
string
This encode/decode abstraction is exposed directly by tokenizer libraries.
Level 4 — Agentic AI Engineer Explanation
LLM Application
      ↓
RAG
      ↓
Tools
      ↓
Agent
      ↓
State / Memory
      ↓
Workflow
      ↓
Multi-Agent System
At nearly every LLM invocation:
System instructions
+
Conversation
+
Retrieved documents
+
Agent state
+
Tool results
        ↓
      TEXT
        ↓
   TOKENIZATION
        ↓
   TOKEN SEQUENCE
        ↓
      LLM
Therefore tokenization indirectly affects:
context capacity
cost
latency
truncation
RAG chunk sizing
tool-output sizing
conversation-history sizing
Tokenization itself does not perform reasoning, retrieval, planning, memory or tool execution.
Why Was Tokenization Needed?
Older approaches
Whole-word model
"booking"
"bookings"
"booked"
"bookable"
could require separate vocabulary entries.
Problem:
Huge vocabulary
+
poor handling of uncommon/unseen words
Character model
b
o
o
k
i
n
g
avoids unknown words but can create longer sequences.
Subword approach
book
ing
tries to balance vocabulary size with sequence length and reusable language pieces. Word-level tokenization requires much larger vocabularies for broad coverage, while BPE can construct unseen words from smaller pieces.
Mental progression
Whole Words
    ↓
Vocabulary problem
    ↓
Characters
    ↓
Very long sequences
    ↓
Subwords
    ↓
Reusable pieces + manageable vocabulary
Complete Internal Working Flow
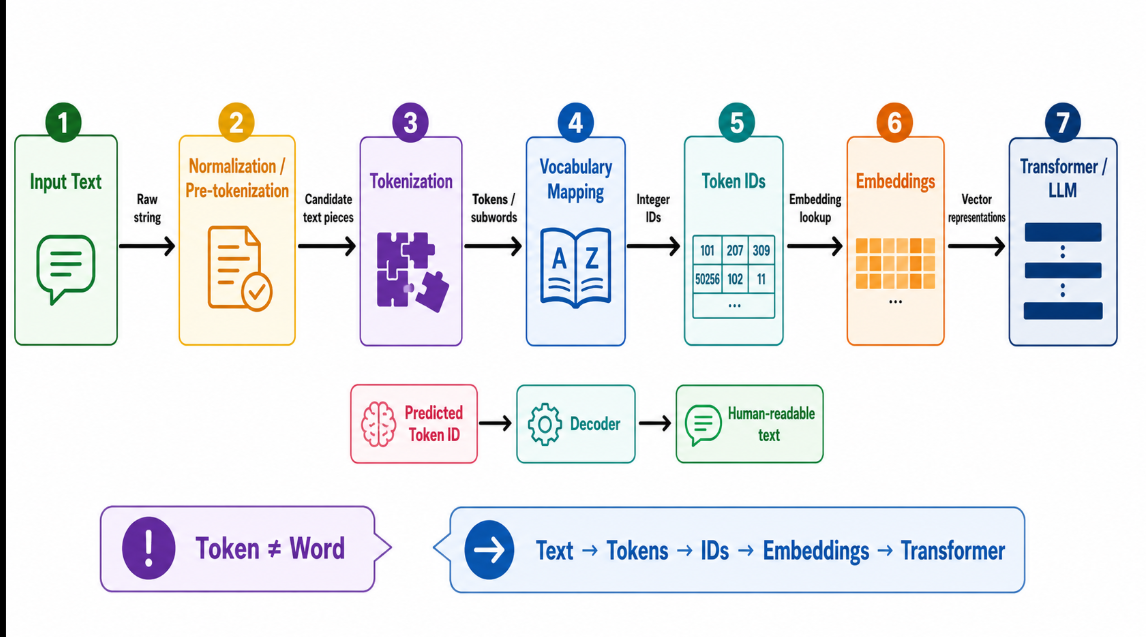
A practical tokenizer pipeline can look like:
User Text
   │
   │ raw string
   ↓
Normalization
   │
   │ normalized string
   ↓
Pre-tokenization
   │
   │ candidate pieces
   ↓
Tokenizer Model
(BPE / WordPiece / etc.)
   │
   │ final tokens
   ↓
Vocabulary Lookup
   │
   │ integer IDs
   ↓
Post-processing
   │
   │ IDs + optional special tokens
   ↓
Token Sequence
   │
   │ next concept
   ↓
Embeddings
   ↓
Transformer
Hugging Face defines the central tokenization pipeline as normalization → pre-tokenization → model → post-processing. Not every tokenizer performs each optional stage in exactly the same manner.
Step 1 — Input
"Book a doctor tomorrow."
Step 2 — Normalization
Possible transformations include Unicode normalization or case handling depending on tokenizer design.
Step 3 — Pre-tokenization
Candidate spans are identified.
Step 4 — Tokenization algorithm
The trained tokenizer rules determine final pieces.
Step 5 — Vocabulary lookup
Each piece maps to an ID.
Step 6 — Post-processing
Some model families add special control tokens.
Step 7 — Token IDs
Those IDs are ready for embedding lookup, which is your next concept.
Important Components / Subconcepts
One Simple Real-World Example
Take a hospital application.
User enters:
"Find a cardiologist in Delhi tomorrow"
Conceptual flow:
User
 │
 │ text
 ↓
Tokenizer
 │
 │ tokens
 ↓
Token IDs
 │
 │ numbers
 ↓
Embeddings
 │
 ↓
Transformer
 │
 ↓
Meaning/context processing
 │
 ↓
Response
Important distinction:
Tokenizer understands:
"How should this text be represented as discrete token IDs?"
Tokenizer does NOT understand:
"Which cardiologist should the patient visit?"
The latter requires model reasoning/application logic.
One Agentic AI Example
User:
"Find a cardiologist tomorrow
and book the earliest available appointment."
Agent flow:
User Request
      ↓
Tokenizer
      ↓
Token IDs
      ↓
Embeddings
      ↓
LLM
      ↓
Decide: search doctors
      ↓
Hospital API Tool
      ↓
Available appointments
      ↓
Tool result converted to prompt/context
      ↓
Tokenizer
      ↓
LLM
      ↓
Decide: book 10:30 AM
      ↓
Booking API
      ↓
Confirmation
      ↓
LLM
      ↓
Final Response
This part IS handled by tokenization
Text ↔ token representation / token IDs
This part is NOT handled by tokenization
❌ deciding which tool to call
❌ reasoning
❌ doctor search
❌ API execution
❌ maintaining durable memory
❌ planning
❌ booking
Compare with Closely Related Concepts
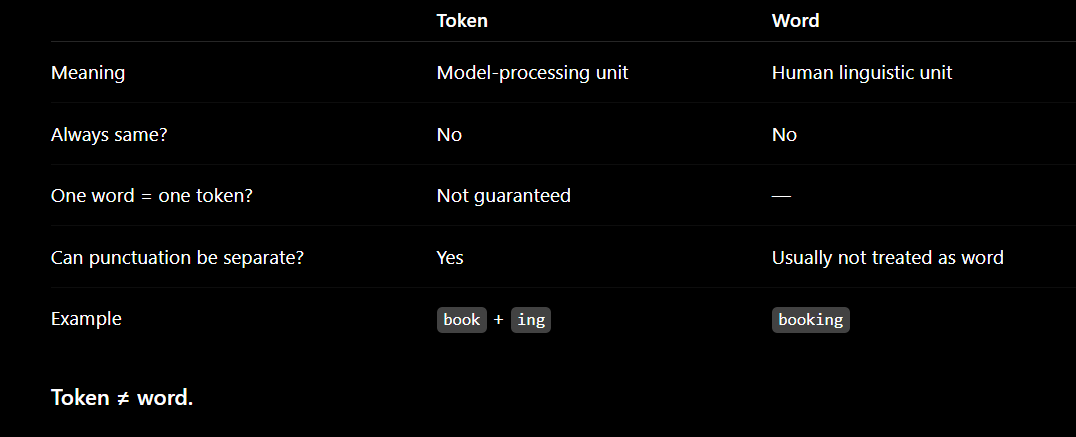
Token vs Word
Token vs Token ID
Tokenization vs Embedding
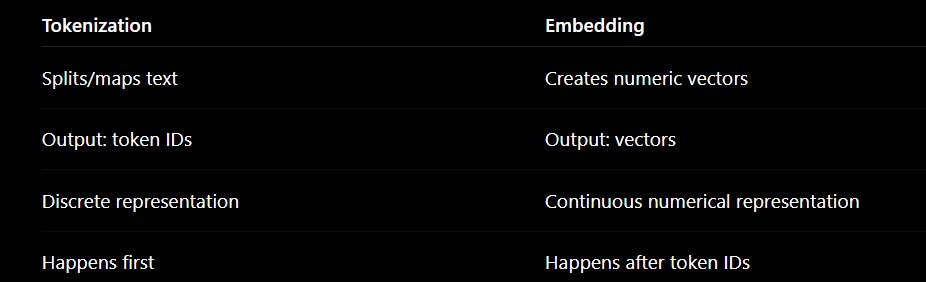
Text
 ↓
Tokenization
 ↓
Token IDs
 ↓
Embedding
 ↓
Vectors
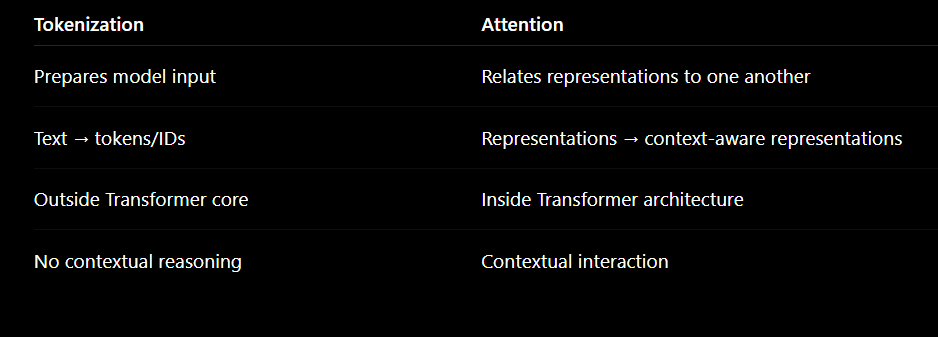
Tokenization vs Attention
Relationship with Previous and Next Concepts
Transformer + Attention
      ↓
tells you how sequence elements interact
      ↓
Tokens / Tokenization
      ↓
defines what those sequence elements initially are
      ↓
Token IDs
      ↓
Embeddings
      ↓
turn IDs into vectors the Transformer can process
What should you already know?
Transformer processes sequences.
Attention allows positions in that sequence to influence one another.
LLM generation proceeds token by token at the output level.
What becomes easier now?
embeddings;
context windows;
prompt length;
next-token prediction;
RAG chunking;
LLM cost analysis;
context management;
agent-history management.
Future Agentic AI concepts depending on this
Prompt engineering
Context management
RAG
Memory retrieval
Tool results
Structured outputs
Agent loops
Cost optimization
Latency optimization
Multi-agent communication
What Should I NOT Learn Now?
This is deliberately important because your goal is engineering rather than ML research.
❌ Train a large tokenizer from scratch
Reason: Not required to build LLM applications.

Learn it later when: You are building/customizing a model or highly specialized domain tokenizer.
❌ Implement production BPE from scratch
Reason: Understanding the idea is enough now.

Learn later when: Studying tokenizer internals or model training.
❌ Derive vocabulary optimization mathematically
Reason: Research/model-training concern.

Learn later when: Working on foundation models.
❌ Deep Unicode normalization internals
Reason: Know that normalization exists; you do not need Unicode research.

Learn later when: Debugging multilingual/tokenizer-specific issues.
❌ GPU tokenizer kernels
Reason: Infrastructure optimization far beyond current needs.

Learn later when: Operating extremely high-throughput inference systems.
❌ Master every tokenizer algorithm
You only need:
BPE       → know reasonably well
WordPiece → recognize
Unigram   → recognize
WordLevel → understand limitation
Hugging Face documents these as distinct tokenizer-model approaches.
Practical Experiments
Experiment 1 — See What an LLM Actually Sees
Goal
Observe that a sentence becomes token IDs.
Input
"I want to book a hospital appointment."
What I Should Do
Encode it with a real tokenizer and print:
original text
token IDs
individual decoded pieces
token count
Expected Output
Something conceptually like:
Text → [ID, ID, ID, ID, ...]
What It Proves
LLM input ≠ raw sentence
Observe
spaces may be attached to pieces;
punctuation may have its own token;
one word may use multiple tokens.
Common Mistake
Assuming every word equals exactly one token.
Experiment 2 — Compare Different Input Styles
Goal
Understand token-count sensitivity.
Inputs
Book a doctor.


BOOK A DOCTOR.


book_a_doctor()


मुझे डॉक्टर बुक करना है
Do
Count tokens for each.
Observe
Different text patterns and languages can tokenize differently because tokenization depends on the tokenizer's vocabulary and rules.
Concept Proven
Character count ≠ word count ≠ token count
Experiment 3 — Token Budget Experiment
Goal
Connect tokenization to production context management.
Build inputs:
Prompt A:
short user request


Prompt B:
same request + huge tool response
Count tokens.
Observe
Prompt A → small context usage


Prompt B → much larger context usage
Concept Proven
Agent tool results consume model context after they are represented as tokens.
-
Debugging / Failure Experiment
Agent receives oversized tool output
Normal input
User:
"Find available doctors tomorrow."


Tool:
5 concise appointment records

↓
Expected:
Agent receives useful context
and chooses an appointment.
Bad input
Tool returns:
2 MB HTML
+ navigation markup
+ scripts
+ 500 irrelevant records
↓
Tokenized context becomes enormous.
↓
Possible observed behavior:
higher latency
higher token consumption
important context may be truncated
relevant signal gets buried
Tokenizer APIs explicitly support truncation/max-length handling because model inputs have sequence-length constraints.
Engineering lesson
Do not immediately blame the LLM.
Check:
Tool Output
     ↓
Cleaning
     ↓
Chunking/filtering
     ↓
Token Count        ← suspect here
     ↓
Context Assembly
     ↓
LLM
Code Only When It Helps Learning
A small tiktoken experiment is enough. OpenAI's tokenizer library exposes encoding, decoding and per-token byte decoding for inspection.
import tiktoken


encoding = tiktoken.get_encoding("o200k_base")


text = "Book a cardiologist appointment tomorrow."


token_ids = encoding.encode(text)


print("Text:")
print(text)


print("\nToken IDs:")
print(token_ids)


print("\nToken count:")
print(len(token_ids))


print("\nIndividual token pieces:")
for token_id in token_ids:
    piece = encoding.decode_single_token_bytes(token_id)
    print(token_id, "->", piece)
Install:
pip install tiktoken
Flow
Input String
     ↓
encoding.encode()
     ↓
Token IDs
     ↓
Inspect each token
     ↓
Count tokens
What you learned
You are no longer imagining that:
LLM reads words.
You can inspect the actual tokenizer representation.
Architecture Diagrams
16.1 Diagram A — End-to-End Pipeline
┌───────────────────────┐
│      Input Text       │
│ "Book appointment"    │
└──────────┬────────────┘
           │ raw string
           ↓
┌───────────────────────┐
│ Normalization /       │
│ Pre-tokenization      │
└──────────┬────────────┘
           │ candidate pieces
           ↓
┌───────────────────────┐
│     TOKENIZATION      │
│ BPE / equivalent     │
└──────────┬────────────┘
           │ tokens
           ↓
┌───────────────────────┐
│  Vocabulary Mapping   │
└──────────┬────────────┘
           │ token IDs
           ↓
┌───────────────────────┐
│     Token Sequence    │
└──────────┬────────────┘
           │ IDs
           ↓
┌───────────────────────┐
│      Embeddings       │
│    NEXT CONCEPT       │
└───────────────────────┘
16.2 Diagram B — Internal Anatomy
┌──────────────────── TOKENIZER ──────────────────────┐
│                                                     │
│ Raw Text                                            │
│    │                                                │
│    │ normalize                                      │
│    ↓                                                │
│ Normalizer                                          │
│    │                                                │
│    │ normalized text                                │
│    ↓                                                │
│ Pre-tokenizer                                       │
│    │                                                │
│    │ candidate pieces                               │
│    ↓                                                │
│ Tokenization Model                                  │
│ BPE / WordPiece / Unigram                           │
│    │                                                │
│    │ final tokens                                   │
│    ↓                                                │
│ Vocabulary Lookup                                   │
│    │                                                │
│    │ token IDs                                      │
│    ↓                                                │
│ Post-processing                                     │
│    │                                                │
│    │ optional special tokens                        │
│    ↓                                                │
│ Final Token-ID Sequence                             │
│                                                     │
└─────────────────────────────────────────────────────┘
Notice: there is no generation loop inside tokenization itself. Generation repetition belongs to LLM inference:
predict token
    ↓
append token
    ↓
new context
    ↓
predict next token
    ↺
until stop condition
16.3 Diagram C — Ecosystem Hierarchy
For technical accuracy, tokenization is not literally a Transformer layer.
Tokenization
      ⊂
LLM Input / Output Pipeline
      ⊂
LLM Application
      ⊂
AI Agent
      ⊂
Agentic AI System
What each outer layer adds:
Tokenization
→ text ↔ model-readable token IDs


LLM pipeline
→ embeddings + Transformer inference + generation


LLM application
→ prompts, business logic, APIs, UI


AI Agent
→ decisions + tools + iterative action


Agentic AI system
→ state + workflows + memory + governance +
  multi-step/multi-agent orchestration
Mental Model
Tokenization = cutting text into model-compatible pieces and assigning those pieces IDs.
Memorize:

Human Text
    ↓
Tokens
    ↓
Token IDs
    ↓
Embeddings
    ↓
Transformer
Or even shorter:
TEXT → PIECES → NUMBERS
Common Misunderstandings
❌ Token = word
✅ Correct
A word can map to one or multiple tokens, depending on the tokenizer.
❌ Token ID = embedding
✅ Correct
Token
↓
Token ID
↓
Embedding vector
❌ Tokenization understands sentence meaning
✅ Correct
Tokenization creates discrete model inputs.
Contextual meaning emerges later through model processing.
❌ Attention tokenizes text
✅ Correct
Tokenization happens before the Transformer receives model-ready representations.
Attention operates on representations corresponding to sequence positions.
❌ The tokenizer is the LLM
✅ Correct
Tokenizer = text interface
LLM = learned neural model
❌ Context window means number of words
✅ Correct
Model context constraints are represented in tokens, not ordinary word counts.
❌ More context is always better
✅ Correct
More context consumes budget and processing; irrelevant context can also hurt application quality.
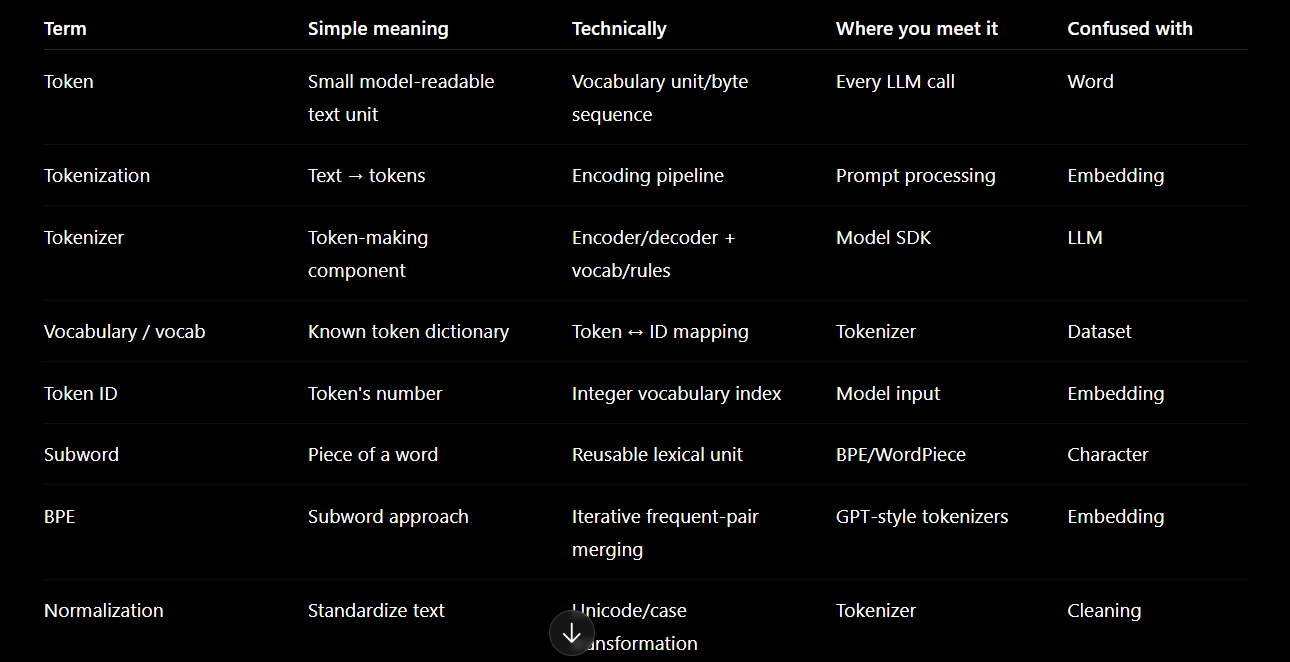
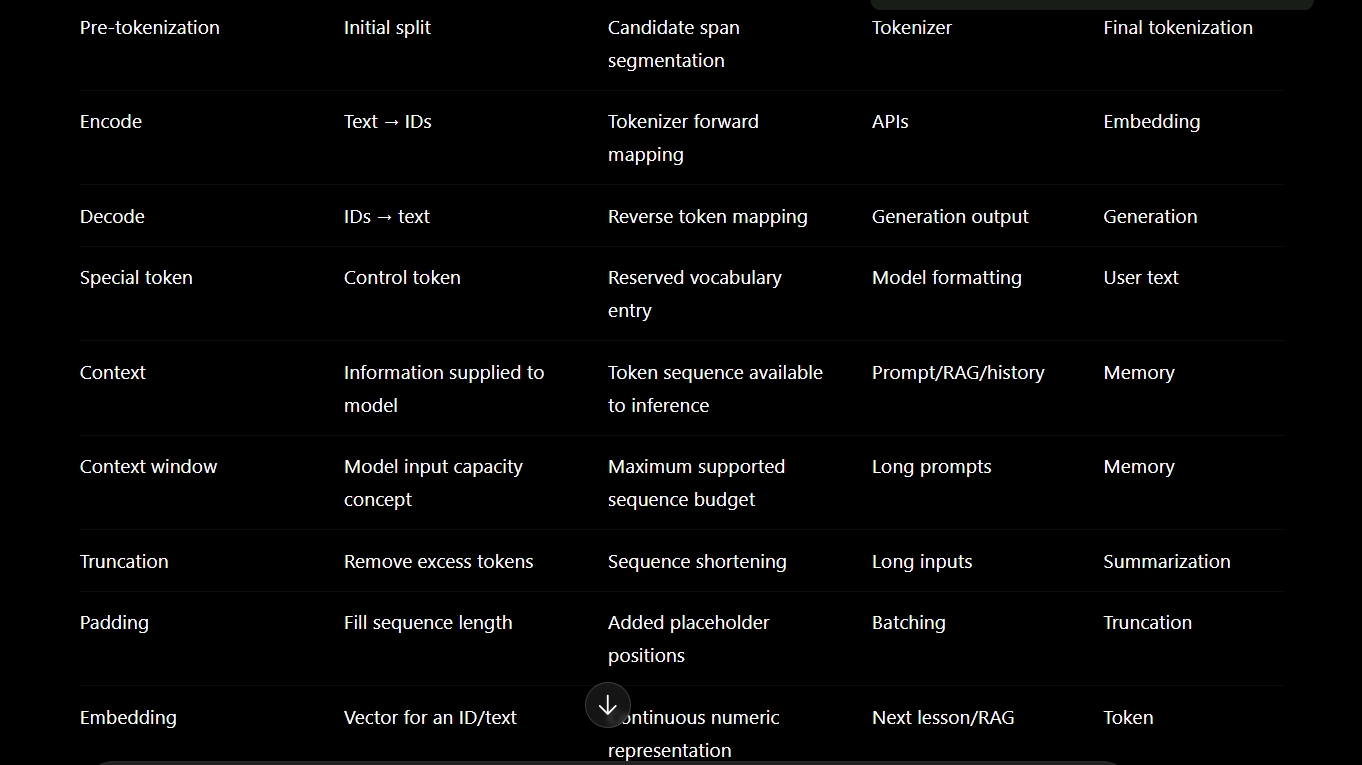
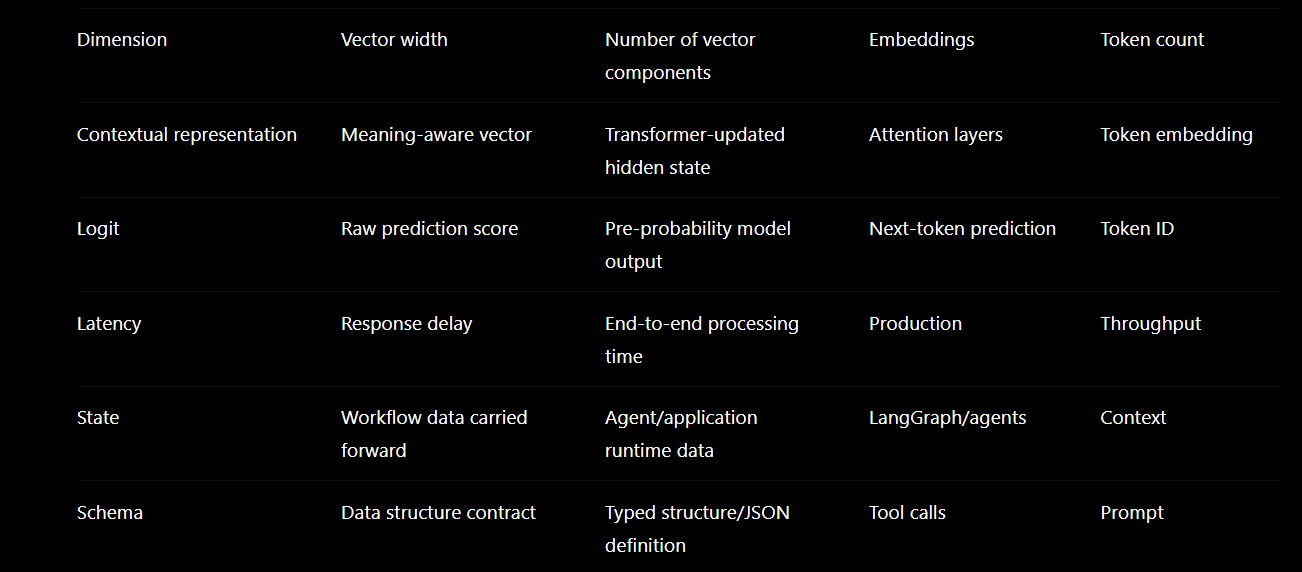
Important Terminology
Contrast Pairs
Token vs Word
Token = unit chosen by tokenizer
Word  = human linguistic unit


Difference:
One word does not necessarily equal one token.


Example:
"tokenization" might be represented using multiple subword tokens.


What breaks if confused:
Your prompt-size estimates become wrong.
Token Representation vs Contextual Representation
Initial token representation
= representation associated with a token before contextual Transformer processing


Contextual representation
= representation after surrounding tokens have influenced it through Transformer layers
Example:
"bank account"
"river bank"
The same lexical token can participate in different contextual representations because surrounding context differs.
Difference:
initial representation
↓ Transformer + Attention
contextual representation
Token vs Embedding
Token = discrete unit
Embedding = numeric vector
Example:
"doctor"
   ↓
token ID
   ↓
[0.18, -0.42, ...]
What breaks:
You may mistakenly think tokenization performs semantic vector search.
Prompt vs Context
Prompt
= instructions/input assembled for a model call


Context
= the broader information represented within the model's active sequence
Agent example:
System instructions
+ user message
+ history
+ retrieved docs
+ tool result
        ↓
active context
Context vs Memory vs State
Context
= what the model can currently see


Memory
= information preserved/retrieved across interactions


State
= structured application/workflow data describing current execution
Example:
state.booking_id = 7821


memory:
"user prefers morning appointments"


context:
current prompt containing selected pieces of both
Architecture vs Model
Transformer = architecture/design family


A trained LLM = learned model built using an architecture
Don't say:
Transformer = every LLM
as though architecture and trained model are identical concepts.
Terms You Should Be Able to Use Naturally
Token
“The tool response adds too many tokens to the next model call.”
Tokenizer
“We need to count this using the tokenizer associated with the target model.”
Token ID
“The tokenizer converts those pieces into token IDs before embedding lookup.”
Vocabulary
“That token ID is only meaningful relative to that tokenizer's vocabulary.”
Context window
“We need to control retrieved documents so the assembled context stays within our model budget.”
Truncation
“Let's verify whether truncation is removing the system instructions or earlier history.”
Embedding
“Token IDs become embeddings before Transformer processing.”
Interview Questions
20.1
Subjective Questions
Q1.** What is a token?** ⭐
Model answer:
A token is a unit produced by a tokenizer for model processing. It may correspond to a word, part of a word, punctuation or another text/byte unit. A token is not automatically the same thing as a word.
Follow-up:
Does one word always equal one token?
Red flag:
“Yes, token means word.”
Q2. What is tokenization? ⭐
Model answer:
Tokenization converts input text into discrete tokens and then IDs that the model's input pipeline can process.
Follow-up:
What comes immediately after token IDs?
Answer:
Embedding lookup/representation.
Q3. Why don't LLMs simply use complete words? ⭐⭐
Model answer:
A pure word vocabulary becomes very large and has trouble with words it has never seen. Subword approaches reuse smaller pieces and provide better vocabulary coverage with a manageable vocabulary size.
Follow-up:
Why not simply use characters?
Red flag:
“Because LLMs cannot understand words.”
Q4. Token vs token ID? ⭐⭐
Model answer:
The token is the discrete textual/byte piece; the token ID is the integer assigned to that piece in a particular vocabulary.
Follow-up:
Is the ID itself semantic?
Answer:
No; it is primarily an index/identifier.
Q5. Explain tokenization end-to-end. ⭐⭐⭐
Model answer:
Text
→ normalization/pre-tokenization where applicable
→ tokenization algorithm
→ tokens
→ vocabulary lookup
→ token IDs
→ optional post-processing
The IDs then continue into the model's representation pipeline.
Follow-up:
Which parts are tokenizer-specific?
Q6. Tokenization vs embedding? ⭐⭐⭐
Model answer:
Tokenization produces discrete tokens/IDs. Embedding converts those IDs or text representations into continuous vectors. Tokenization therefore occurs logically before embedding.
Follow-up:
Which one produces vectors?
Answer: Embeddings.
Q7. Tokenization vs Attention? ⭐⭐⭐
Model answer:
Tokenization prepares the sequence. Attention operates later inside the Transformer and computes interactions between sequence representations. They solve completely different problems.
Follow-up:
Can the tokenizer determine which earlier word matters most?
Answer: No.
Q8. Why does an Agentic AI engineer care about tokenization? ⭐⭐⭐⭐
Model answer:
Because every LLM call has a context budget. Agent prompts can include instructions, history, RAG documents, state and tool results. Understanding tokenization lets me estimate context consumption, detect truncation, reduce unnecessary context and control latency/cost.
Follow-up:
Which agent component often causes unexpected context growth?
Good examples: tool outputs/history/retrieved documents.
Q9. Does understanding tokenization mean an Agentic AI engineer must implement BPE from scratch? ⭐⭐⭐
Model answer:
No. I need to understand what tokenization does, inspect tokens, measure token usage and debug context problems. Implementing tokenizer algorithms is normally model-training or research work.
Follow-up:
When would you learn it deeply?
Q10. Your agent suddenly becomes expensive after adding a web-search tool. What do you inspect? ⭐⭐⭐⭐
Model answer:
I would inspect how much tool output is inserted into subsequent prompts, measure its token count, remove irrelevant fields/content, and check whether history and RAG results are also accumulating.
Follow-up:
Would changing temperature solve this?
Red flag:
“Yes, lower temperature reduces input tokens.”
Q11. Why can two similar-looking strings have different token counts? ⭐⭐⭐⭐
Model answer:
Tokenization depends on the tokenizer's learned vocabulary and segmentation rules. Spaces, punctuation, case, scripts and uncommon character sequences can create different token boundaries.
Follow-up:
Should we estimate tokens using len(text.split())?
Answer: No.
Q12. Where exactly does tokenization sit in an agent architecture? ⭐⭐⭐⭐⭐
Model answer:
It is part of the LLM interface/input-output pipeline, not the agent's planning layer. Whenever the agent sends assembled context to a model, that text is tokenized. The agent then adds higher-level behavior such as state, tools, decisions and loops.
Follow-up:
What does the outer agent layer add that tokenization cannot?
Red flag:
“Tokenization chooses the agent's next tool.”
20.2
Objective Questions
Q1. Which statement is correct? ⭐
A) Every token is a word
B) A word may contain multiple tokens
C) Every character is always a token
D) Tokens are embeddings
Answer: B
Why others are wrong:
A: token ≠ word.
C: tokenizer-dependent.
D: embeddings come later.
Q2. What normally follows token IDs in the model-input pipeline? ⭐⭐
A) SQL query
B) Embedding representation
C) Agent memory
D) MCP server
Answer: B
A: application/tool behavior.
C: higher-level agent concept.
D: tool interoperability, not model representation.
Q3. Which component maps tokens to integer IDs? ⭐⭐
A) Vocabulary
B) Attention
C) RAG
D) Agent planner
Answer: A
B operates on representations.
C retrieves external information.
D selects actions/steps.
Q4. Which is NOT a tokenizer's responsibility? ⭐⭐⭐
A) Breaking text into token units
B) Mapping tokens to IDs
C) Choosing which API an agent should call
D) Decoding token IDs
Answer: C
The agent/orchestrator handles tool decisions.
Q5. Why can large tool outputs be problematic? ⭐⭐⭐⭐
A) Tools cannot return text
B) They can consume a large portion of model context
C) Tokenizers stop working after tool calls
D) Embeddings become strings
Answer: B
Q6. Which statement is most accurate? ⭐⭐⭐⭐
A) Tokenization and attention are identical
B) Tokenization performs semantic retrieval
C) Tokenization prepares units; attention contextualizes representations
D) Attention generates token IDs before tokenization
Answer: C
This directly diagnoses the common Tokenization-vs-Attention confusion.
20.3
The One Question That Decides the Interview
Question
“Explain how a user sentence becomes something a Transformer can process, and tell me why that knowledge matters when building an AI agent.”
Under-60-second answer
A user starts with a text string. A tokenizer converts that string into discrete tokens using its vocabulary and tokenization rules, then maps those tokens to integer IDs. Those IDs are converted into embeddings, which enter the Transformer and become context-aware representations through its layers. During generation the model predicts further token IDs, which are eventually decoded back to text. As an Agentic AI engineer, I normally don't implement the tokenizer myself, but I need to understand it because prompts, RAG documents, conversation history and tool outputs all consume token budget, affecting context limits, truncation, latency and cost.


Top comments (0)