
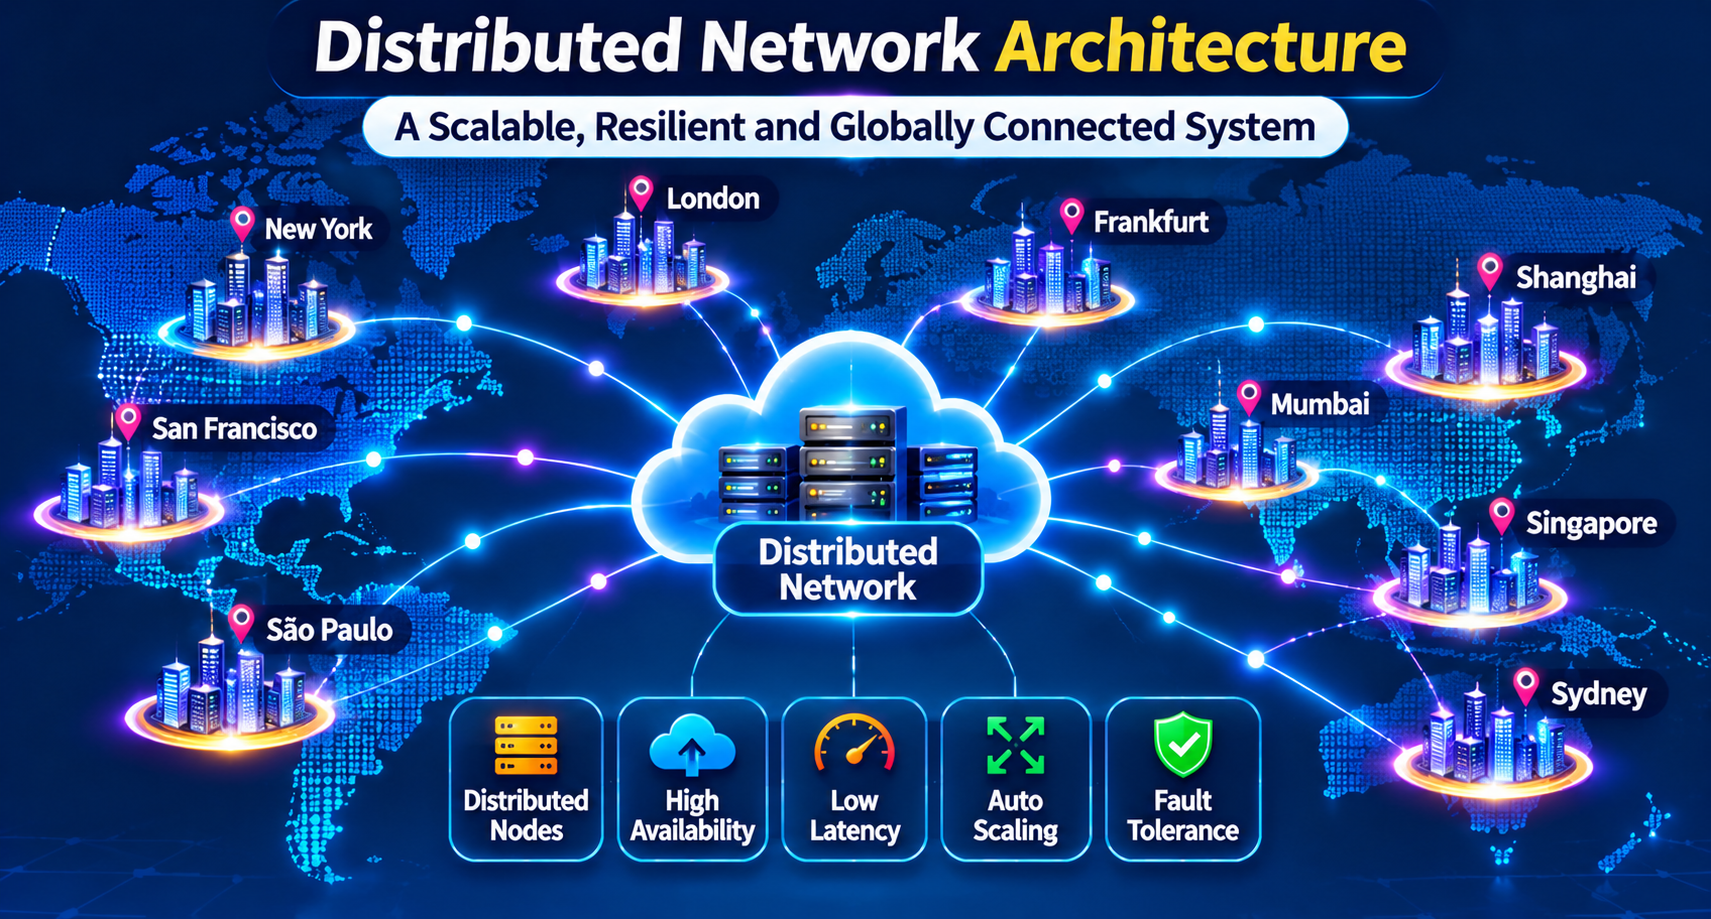
Introduction – The Infrastructure Challenge
Operating an event marketplace requires far more than a functional web application serving static pages. Platforms designed to handle Online Event Ticket Booking China must contend with extreme traffic volatility. When millions of users simultaneously attempt to secure seats for high-demand Upcoming Events in China, underlying cloud services face severe load pressure.
Beyond serving basic search queries, the system must process real-time seat locks, coordinate event organizer publishing dashboards, handle financial transaction gateways, and maintain transactional integrity across inventory databases. A failure in any of these components during a flash sale leads to frustrated users, overselling, and severe revenue loss. Achieving high availability demands a disciplined convergence of modern DevOps automation, Site Reliability Engineering (SRE) practices, and robust cloud-native architecture.
Understanding the Platform Architecture
To contextualize our operational challenges, consider an illustrative microservices-based architecture for an event discovery marketplace. This model serves as a hypothetical blueprint rather than a confirmed implementation of MyEventsNow China.
graph TD
    User[Client / Mobile App] --> CDN[Global CDN / Edge Layer]
    CDN --> API[API Gateway / Load Balancer]
    API --> Auth[Auth & Session Service]
    API --> Search[Search & Discovery Service]
    API --> Booking[Ticket Inventory & Booking Engine]
    API --> Org[Organizer Management Service]

    Search --> DB_Search[(Search Cluster)]
    Booking --> DB_Primary[(Primary Transaction DB)]
    Booking --> Redis[(Distributed Cache / Queue)]
    Org --> DB_Org[(Organizer DB)]

Booking --> Payment[External Payment Gateway]- Frontend and Edge Layer: Content Delivery Networks (CDNs) cache static assets, city landing pages, and general schedules for Shanghai Events and Tickets and Beijing Events and Tickets.
- API Gateway: Acts as the single entry point, handling rate limiting, request routing, and JWT validation.
- Search and Discovery Service: Powers city-based filtering, categorization for Concerts, Festivals, Workshops, and exhibition listings.
- Ticket Inventory Service: Manages atomic seat allocation, expiration timers, and database transactions for Concert Tickets in China and Business Conferences in China.
- Payment Integration Boundaries: Decouples order placement from third-party payment settlement to prevent cascading failures if a gateway experiences latency.
CI/CD Pipeline for Continuous Delivery
Continuous delivery in a ticketing ecosystem must balance deployment velocity with rigorous risk mitigation. Because the platform acts as an Event Registration Platform China and Event Ticketing Software China, a buggy deployment during peak hours can disrupt thousands of active transactions.
- Source Control & Git Workflows: Trunk-based development with short-lived feature branches, protected main branches, and mandatory code reviews.
- Automated Testing: CI pipelines run static code analysis, unit tests, integration tests for booking workflows, and contract testing between microservices.
- Staging and Production Environments: Automated promotion pipelines that build immutable container images, pushing them first to staging clusters that mirror production topologies.
- Rollback Strategies and Release Approvals: Utilizing blue-green or canary deployments. If error rates spike past predefined thresholds during a canary release, the service mesh automatically routes traffic back to the stable baseline version.
Handling Sudden Traffic Spikes
Imagine a hypothetical scenario: a massively popular pop star announces a stadium tour, releasing Concert Tickets in China in Shanghai next Friday at 10:00 AM. Within milliseconds, millions of fans flood the platform.
To survive this surge, engineers implement multi-layered mitigation strategies:
- Horizontal Scaling: Kubernetes Horizontal Pod Autoscalers (HPA) scale out stateless API pods based on custom metrics like queue depth and request latency, rather than CPU utilization alone.
- Load Balancing: Layer 7 load balancers distribute requests evenly across availability zones.
- Caching and Edge Offloading: Event metadata and static venue maps are cached aggressively at the edge CDN.
- Queue-Based Request Processing: Instead of allowing millions of threads to hammer the primary database, incoming reservation requests are pushed to a high-throughput message broker (such as Apache Kafka or Redis streams) to be processed asynchronously in strict FIFO order.
- Database Connection Management: PgBouncer or similar connection poolers prevent database exhaustion by multiplexing client connections.
- Rate Limiting & Token Buckets: IP- and user-based rate limiting blocks automated scripts and bot nets attempting to scalp tickets.
- Trade-Offs: Introducing queues and aggressive caching improves availability and prevents database crashes, but introduces eventual consistency challenges. Users may see cached inventory counts that are slightly out of sync until their reservation request is fully processed by the core engine.
Monitoring and Observability
SRE teams rely on the "Three Pillars of Observability"—metrics, logs, and traces—to maintain visibility during high-stakes events.
Key telemetry signals include:
- API Latency and Error Rates: Tracking HTTP 5xx and 4xx status codes, specifically monitoring checkout and payment callback endpoints.
- Booking Success Rates: Measuring the ratio of successful ticket reservations to total checkout attempts in real time.
- Database Performance: Monitoring connection pool utilization, slow query logs, and transaction lock wait times.
- Queue Delays: Measuring lag time between a user submitting a booking request and the inventory service processing it.
- Centralized Logging & Distributed Tracing: Structured JSON logs aggregated via Fluentbit/Elasticsearch, combined with OpenTelemetry distributed traces to isolate bottlenecks across microservice boundaries when a payment callback fails or times out.
Reliability and Incident Management
Even with robust scaling, anomalies happen.
- Failure Isolation: Circuit breakers (using patterns implemented in service meshes or libraries like Resilience4j) isolate failing payment gateways, preventing downstream thread starvation.
- Backups and Recovery: Automated snapshot routines for primary databases with verified point-in-time recovery (PITR) procedures.
- Hypothetical Incident: During a major festival ticket drop, engineers notice an unexpected surge in database connection timeouts and failed payment confirmations. The on-call SRE immediately activates rate-limiting rules at the API gateway to shed bot traffic, scales up the database read replicas, and diverts non-critical search traffic to static cache fallbacks, restoring service within minutes.
- Recovery Objectives: Defining strict Recovery Time Objectives (RTO < 15 minutes) and Recovery Point Objectives (RPO < 1 minute) for core transactional state data.
Security and DevSecOps
Protecting user personal data and financial workflows requires a defense-in-depth posture.
- Secrets Management: Utilizing secure secret stores (such as HashiCorp Vault or cloud native secret managers) to inject database credentials and payment API keys at runtime without hardcoding them in repositories.
- API Security & Encryption: Enforcing strict TLS 1.3 across all endpoints, validating input payloads to prevent SQL injection or cross-site scripting, and enforcing OAuth2/OIDC token verification.
- Vulnerability Management: Automated container image scanning within CI/CD pipelines to catch CVEs in base images and third-party libraries before production deployment.
Infrastructure Automation and GitOps
Manual infrastructure provisioning introduces configuration drift and human error.
- Infrastructure as Code (IaC): Defining cloud networks, Kubernetes clusters, and database instances using Terraform or OpenTofu.
- GitOps Workflows: Utilizing tools like ArgoCD to continuously reconcile cluster state with declarative manifests stored in Git repositories. If an engineer manually modifies a Kubernetes deployment in production, the GitOps controller automatically detects the drift and rolls back the unauthorized change, ensuring strict environment consistency.
Practical DevOps Implementation Roadmap
- Infrastructure and Application Assessment: Audit existing services, containerize legacy components, and map out external API dependencies.
- CI/CD Pipeline Establishment: Implement automated testing, container builds, and staging environment promotion workflows.
- Monitoring and Observability Implementation: Deploy Prometheus, Grafana dashboards, centralized logging, and OpenTelemetry tracing.
- Scalability and Performance Testing: Conduct rigorous load testing using distributed testing frameworks to simulate millions of concurrent users attempting to List Your Event in China or Sell Event Tickets Online China.
- Security Integration: Implement static analysis, secret scanning, and automated vulnerability gating in code repositories.
- Reliability Testing and Continuous Improvement: Perform regular chaos engineering experiments (e.g., terminating database nodes or blocking payment gateways) to validate system resilience.
Key Engineering Lessons
- Avoid Database Lock Contention: Rely on asynchronous queue processing rather than direct synchronous database locks for high-volume inventory updates.
- Embrace Edge Caching: Offload static and semi-dynamic read requests to CDNs to protect core infrastructure.
- Isolate Failure Domains: Use circuit breakers and bulkhead patterns so a failing third-party payment service does not take down the entire event discovery portal.
- Automate Drift Detection: Use GitOps to maintain absolute state parity between code repositories and production cloud infrastructure.
- Test Under Realistic Load: Synthetic load tests must mirror real-world traffic distributions, including sudden flash-sale spikes.
Conclusion
Operating a reliable event marketplace demands relentless attention to infrastructure design, automation, and observability. By combining rigorous CI/CD pipelines, elastic container scaling, distributed asynchronous queues, and proactive SRE incident management, engineering teams can build resilient platforms capable of delivering seamless experiences during the most demanding traffic surges.


Top comments (0)